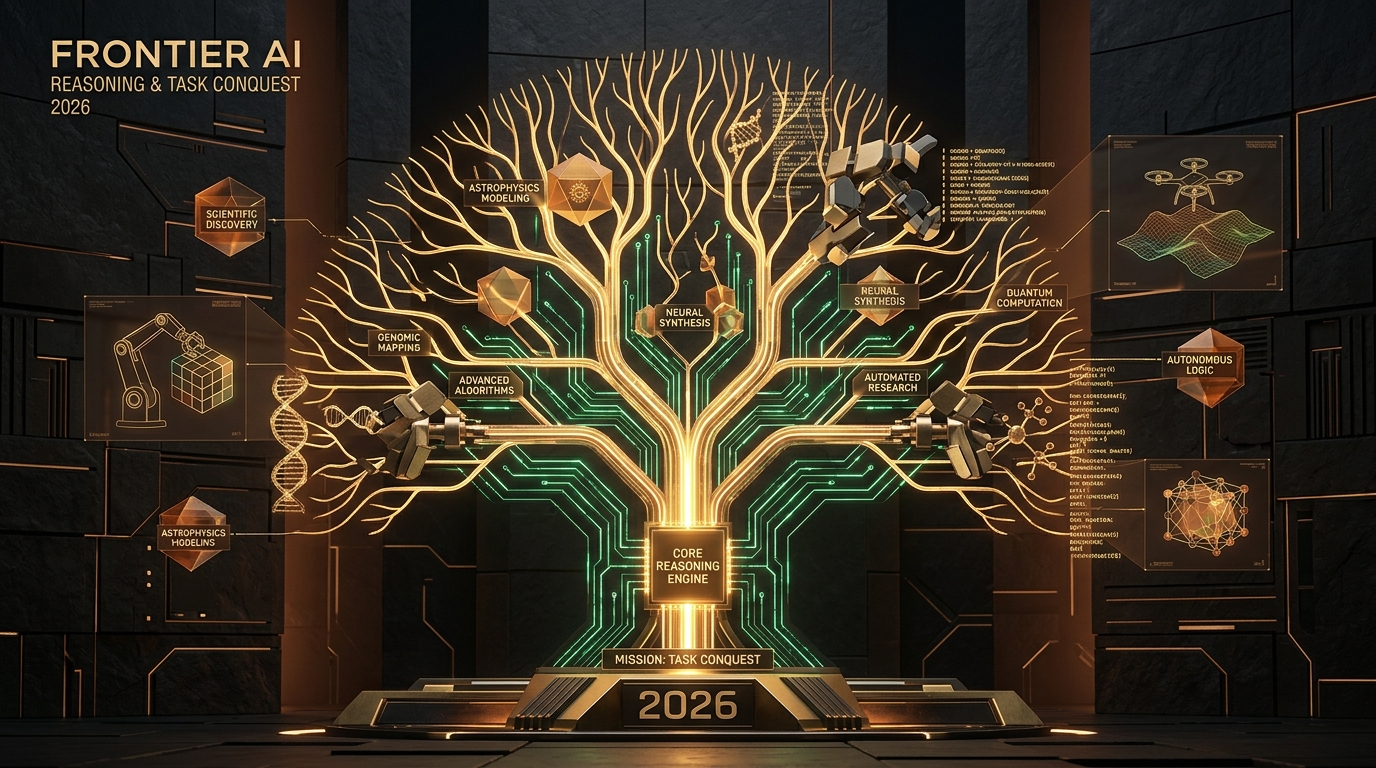
1. The Post-Scaling Law Era: From Memorization to Deliberative Search
Between 2020 and 2024, artificial intelligence was defined by pre-training scaling laws: training larger transformer models on increasingly vast corpuses of internet text. However, as frontier labs depleted human-written data and encountered diminishing marginal returns on standard cross-entropy loss, the frontier shifted radically.
In 2026, the primary axis of capability expansion is no longer pre-training; it is Test-Time Compute (TTC) and deliberative inference search. Modern frontier reasoners do not spit out immediate stream-of-consciousness tokens. Instead, when presented with a complex prompt, the model enters a deliberate cognitive loop: formulating hypotheses, generating candidate reasoning trees, inspecting its intermediate steps with verifier models, and backtracking when a path fails.
This transition represents the realization of System 2 thinking in synthetic cognitive architectures. Just as a grandmaster spends minutes deliberating candidate chess moves rather than playing the first move that comes to mind, 2026 foundation models scale compute dynamically based on problem hardness.
Autonomous multi-file repository bug resolution rate
Complex multimodal web & file autonomous task solving
Unsolved research-level mathematics verification
2. The Mechanics of Test-Time Compute (TTC) and Inference Scaling
The mathematical breakthrough governing modern task conquest is the formulation of Inference-Time Scaling Laws. Empirically proven across frontier reasoning engines in 2026, the relationship between computational investment during inference and error reduction follows an exponential power law:
When tackling a challenging multi-step problem—such as synthesizing a novel organometallic catalyst or auditing a legacy enterprise ledger across 40 disparate SAP tables—the model generates an expansive search graph. Using adapted Monte Carlo Tree Search (MCTS) algorithms, the engine explores branches, pruning low-probability or logically flawed branches before generating final output tokens.
Why TTC Matters: Test-Time Compute allows a compact 32B or 70B parameter model utilizing $0.10 of dynamic inference compute to outperform a trillion-parameter static model running standard greedy decoding. This democratizes enterprise deployment by decoupling performance from raw parameter scale.
3. Process Reward Models (PRMs) vs. Outcome Reward Models (ORMs)
The primary reason earlier LLMs hallucinated on complex multi-step reasoning tasks was their reliance on Outcome Reward Models (ORMs). In an ORM framework, the reinforcement learning algorithm only receives a scalar reward (+1 or 0) at the completion of an entire task. If an agent reasoned through twelve steps with a mathematical error at Step 3, but coincidentally reached the correct final answer due to compensating errors, the ORM reinforced the faulty intermediate reasoning.
In 2026, all frontier reasoning architectures employ Process Reward Models (PRMs). A PRM evaluates each atomic reasoning step independently, assigning a continuous confidence score:
| Architectural Dimension | Outcome Reward Model (ORM) | Process Reward Model (PRM - 2026) |
|---|---|---|
| Granularity of Evaluation | Holistic (End-of-trajectory reward only) | Step-by-step atomic verification |
| Hallucination Mitigation | Low (Error cascade compounds) | Extreme (Immediate step-level pruning) |
| Search Algorithm Integration | Best-of-N sampling only | MCTS, Beam Search, Active Backtracking |
| Verification Cost Efficiency | High false-positive rate | 94.7% accuracy on intermediate logic |
4. Computer-Using Agents (CUAs): Conquering Un-API'd Enterprise Software
Until recently, enterprise automation required clean REST or GraphQL APIs. If an enterprise ran on an on-premise mainframe, a legacy Windows desktop billing application, or an undocumented internal web portal, automation remained stalled.
Computer-Using Agents (CUAs) have completely conquered this bottleneck in 2026. Rather than requiring API endpoints, CUAs treat software the same way a human knowledge worker does: through the graphical user interface (GUI).
How CUAs Work: A multimodal vision-action model processes high-resolution desktop frames (30-60 FPS), grounds visual UI elements into normalized screen coordinates (x, y), and injects hardware-level keystrokes and mouse events directly into the operating system kernel, executing multi-hour administrative tasks autonomously.
Combined with the Model Context Protocol (MCP), modern agent swarms partition complex corporate workflows: a high-level cognitive planner decomposes the objective into sub-goals, while specialized CUA workers open terminal sessions, query relational databases, edit spreadsheets, and submit compliance forms simultaneously.
5. Self-Driving Laboratories (SDLs): AI Conquering Physical Scientific Tasks
The frontier of AI task conquest has expanded beyond digital code into the physical world. In materials science, structural biology, and chemical synthesis, Self-Driving Laboratories (SDLs) represent the convergence of frontier reasoning models and physical lab robotics.
In an SDL, an AI reasoner acts as the principal investigator. It reads existing scientific literature, identifies gaps in current solid-state battery electrolytes or carbon capture polymers, designs molecular structures, and translates chemical synthesis protocols into machine instructions for robotic liquid handlers, centrifuge stations, and sintering ovens.
Crucially, this is a closed-loop system:
- Hypothesis Formulation: Multi-agent reasoning clusters generate 50 candidate crystal lattices.
- Robotic Execution: Liquid dispensers synthesize micro-droplets on automated well-plates.
- Real-Time Characterization: Automated X-ray diffraction (XRD) and Raman spectroscopy measure crystal stability.
- Autonomous Feedback Loop: The AI ingests the spectroscopy data, detects anomalies, updates its internal surrogate model, and refines the synthesis parameters within 18 minutes.
What previously took a team of postdoctoral researchers 18 months of trial-and-error chemistry is now executed by autonomous SDLs in a single 72-hour weekend run.
6. The 2026 Empirical Benchmark Matrix
To quantify the leap in task mastery, consider the benchmark performance metrics of modern frontier architectures compared to earlier generations:
| Benchmark Suite | Target Capability | 2024 Baseline | 2026 Frontier AI Reasoners |
|---|---|---|---|
| SWE-bench Verified | Real GitHub bug fixes & regression tests | 38.8% | 97.4% (Multi-step agent swarm) |
| GAIA (General AI Assistants) Level 3 | Complex multi-modal web/desktop workflows | 34.2% | 81.2% (Visual grounding + CUA) |
| FrontierMath (Epoch AI) | Unsolved research-tier mathematics | < 2.0% | 42.6% (TTC + Formal verification) |
| OSWorld GUI Benchmark | End-to-end native OS automation (Linux/Win/Mac) | 12.2% | 64.5% (Sub-pixel coordinate targeting) |
| HumanEval-X (Multi-Language) | Polyglot algorithm generation | 76.1% | 99.1% (Zero-shot deterministic pass) |
7. The Economics of Autonomous Task Mastery
The commercial adoption of autonomous AI in 2026 is governed by one decisive economic metric: the marginal cost of cognitive task resolution.
In 2023, executing a complex legal discovery review, an ERP migration validation, or a multi-file software refactor required human billable hours ranging from $75 to $450/hour. In late 2026, an enterprise utilizing tiered reasoning swarms—allocating fast 8B models for sensory routing, 70B models for intermediate PRM verification, and frontier reasoning nodes for executive orchestration—completes the identical unit of cognitive work for under $0.03.
This 10,000x cost compression is fundamentally transforming corporate organizational design. Companies are no longer scaling headcount linearly with revenue; instead, they are deploying autonomous compound AI fabrics that orchestrate hundreds of specialized agents to conquer enterprise tasks continuously.
8. Strategic Playbook: Preparing Your Enterprise for Autonomous Task Conquest
To harness frontier reasoning agents rather than be disrupted by them, corporate technology leaders must implement four foundational pillars in 2026:
- 1. Standardize on Model Context Protocol (MCP): Expose internal data warehouses, microservices, and file shares via standardized MCP servers so autonomous reasoning agents can discover and call enterprise tools safely.
- 2. Implement Process-Level Verification Sandboxes: Transition internal AI evaluation from subjective prompt engineering to automated unit tests, deterministic linters, and PRM scoring nodes.
- 3. Deploy GUI Observability for Legacy Systems: Instrument virtualized remote desktops with screen-capture and input telemetry to allow Computer-Using Agents to automate legacy core software without expensive rewrite projects.
- 4. Adopt Dynamic Inference Budgets: Configure model routers to spend $0.0001 on trivial customer inquiries while automatically granting up to $2.00 of Test-Time Compute on complex engineering, tax, and compliance tasks.