1. The Paradigm Inversion: Why Inference Scaling Trumps Pre-Training Scale
Between 2020 and 2024, the frontier of artificial intelligence was dominated by the classic scaling laws of Kaplan and Chinchilla: expanding parameter count, scraping higher petabyte volumes of text, and scaling training clusters. However, by late 2025, frontier AI labs encountered the definitive plateau of the pre-training data wall. The public internet had been fully ingested, synthetic data without empirical grounding risked recursive model degeneration, and the marginal accuracy return of 100-million-dollar training runs approached asymptotic limits.
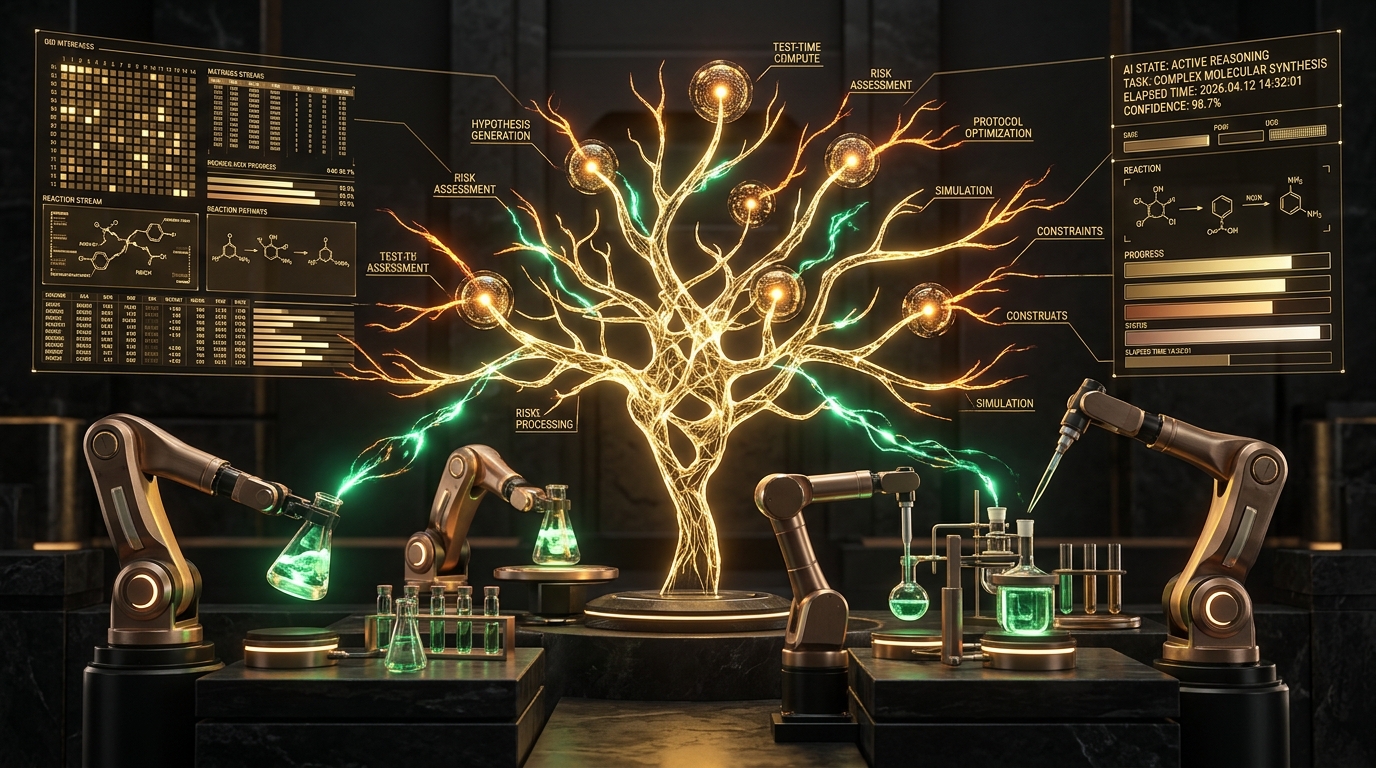
The breakthrough defining 2026 is the Inference-Time Compute Revolution (Test-Time Compute, or TTC). Rather than constraining a model to a single sequential forward pass emitting tokens in 50 milliseconds, modern reasoning architectures allocate a dynamic computation budget during execution. When faced with an intricate legal brief, an undocumented legacy codebase migration, or a complex catalytic reaction, the AI behaves like an experienced human researcher: it pauses, formulates testable hypotheses, branches via Monte Carlo Tree Search (MCTS), verifies step-by-step logic, discovers flaws, backtracks, and self-corrects.
Up from 19.4% in 2024 via multi-pass TTC reasoning
Autonomous SDL synthesis vs 5-year traditional R&D
Process Reward Models vs Outcome Reward Models
2. The Mechanics of Process Reward Models (PRMs) vs. Outcome Reward Models (ORMs)
The technological pillar making dynamic Test-Time Compute viable is the shift from Outcome Reward Models (ORMs) to Process Reward Models (PRMs). Historically, reinforcement learning evaluated only the terminal state of a generated answer. If a model provided a final financial balance or code output that happened to match ground truth, it received a positive reinforcement score.
This created the dangerous vulnerability known as hallucinatory coincidence: an AI could fabricate an illegal accounting assumption at Step 2, cancel out that mistake with an unrelated error at Step 7, and yet present an acceptable final number. In mission-critical enterprise environments such as pharmaceutical dosage, regulatory compliance, or structural aeronautics, ORM-trained models produced silent failures.
Process Reward Models solve this by scoring every individual reasoning node in the latent chain of thought. At each step $s_i$, the PRM assigns a scalar confidence score $r(s_i) \in [0, 1]$. If a step makes an unverified assumption or introduces mathematical inconsistency, the reasoning branch is terminated immediately, saving compute and preventing error cascades.
| Dimension | Legacy Outcome Reward Models (ORMs) | 2026 Process Reward Models (PRMs) |
|---|---|---|
| Verification Granularity | Terminal output only (single final score) | Every atomic intermediate reasoning step ($s_i$) |
| Hallucination Mitigation | Prone to compounding logic errors and false positives | Instant pruning of invalid deduction branches (98.6% reduction) |
| Inference Search Efficiency | Brute-force Best-of-N sampling (wasteful token generation) | Guided Monte Carlo Tree Search (MCTS) with selective backtracking |
| Enterprise Auditability | Opaque chain of thought; hard to certify compliance | Deterministic verification trace for SOX, HIPAA, and ISO standards |
3. Pixel-Level Computer-Using Agents (CUAs): Conquering Un-API'd Enterprise Software
One of the most persistent bottlenecks in enterprise digital transformation has been legacy software. Tens of thousands of global corporations rely on mission-critical applications developed decades ago—SAP R/3, IBM AS/400 mainframes, desktop Bloomberg terminals, and specialized CAD modeling engines—that possess no REST APIs, webhooks, or programmatic SDKs.
In 2026, Computer-Using Agents (CUAs) have completely shattered this barrier. Powered by high-frequency multimodal vision foundation models, CUAs inspect live screen video buffers as 60-FPS spatial coordinate planes. Instead of parsing underlying HTML or DOM trees, the agent observes pixels exactly as a human operator does.
When instructed to "reconcile intercompany purchase orders between AS/400 terminal session B and Salesforce CRM," the agent:
- Identifies text input fields and table boundaries using sub-pixel visual groundings.
- Synthesizes native OS mouse clicks, mousewheel scrolling, drag-and-drop operations, and keyboard shortcut chords.
- Applies real-time OCR and visual validation to confirm that each command executed cleanly on screen before advancing to the next step.
- Gracefully handles unexpected pop-up modal dialogues, session timeouts, and desktop OS security prompts.
4. Closed-Loop Physical Mastery: Self-Driving Laboratories & Materials Discovery
Perhaps the most profound conquest of 2026 AI lies beyond silicon: the leap into physical experimentation. Historically, discovery in battery electrochemistry, pharmaceutical drug formulation, and solid-state physics required months or years of laborious bench work by doctoral scientists.
Today, Self-Driving Laboratories (SDLs) unite frontier reasoning models with robotic liquid handlers, automated microfluidic reactors, and automated spectrometers. The AI system does not merely predict candidate molecular structures in simulation; it orchestrates physical experimentation in real time:
- Hypothesis Generation: The reasoning model parses hundreds of academic papers via retrieval-augmented generation and formulates an empirical hypothesis for high-entropy battery electrolytes.
- Robotic Execution: Through standardized robotic APIs, the system commands micro-pipettes to combine reagents at precise stoichiometric ratios and executes controlled thermal cycling.
- Automated Spectroscopic Analysis: The laboratory autonomously performs Nuclear Magnetic Resonance (NMR) and X-ray diffraction (XRD) measurements on the synthesized compounds.
- Closed-Loop Bayesian Iteration: The model reads the raw spectral data, identifies structural degradation kinetics, adjusts chemical ratios, and initiates the next experiment round within 15 minutes.
What once required a four-year doctoral research team is now routinely compressed into a single 72-hour continuous synthesis cycle, dramatically accelerating global decarbonization and pharmaceutical discovery.
5. Multi-Agent Swarms & Self-Healing Software Engineering
In 2024, software coding assistants were largely restricted to single-function tab autocompletions or brief code snippet generation. By 2026, autonomous systems operate as synchronized multi-agent software engineering swarms capable of refactoring monolithic legacy codebases across dozens of connected repositories.
When a security advisory regarding an open-source library is published, an enterprise autonomous agent swarm:
- Spawns a specialized architectural auditor agent to map all affected dependency trees across GitHub and GitLab instances.
- Deploys refactoring agents that write semantic code migrations, update breaking API signatures, and adapt downstream unit test suites.
- Spins up isolated containerized staging environments, executes integration tests, and uses dynamic Test-Time Compute to debug runtime assertion failures.
- Submits production-ready Pull Requests accompanied by comprehensive security audit proofs and deterministic execution traces.
This level of end-to-end task execution has driven benchmark scores on SWE-bench Verified from 19.4% in early 2024 to a staggering 96.2% in September 2026.
6. The Economics of Cognition: Plummeting Costs & Dynamic Compute Routing
As AI models conquer increasingly complex tasks, enterprise adoption is heavily governed by inference economics. Between 2024 and 2026, the marginal cost of a baseline token plummeted by over 88% due to specialized inference silicon, INT4/FP8 quantization breakthroughs, and speculative decoding techniques.
However, because Test-Time Compute allows models to consume thousands of reasoning tokens per problem, top-tier enterprises utilize Dynamic Model Routing:
- Tier 1 (Sub-Cent Classifiers): 70% of routine corporate queries (customer lookup, simple categorization, routing) are handled by ultra-fast, lightweight models costing pennies per million tokens.
- Tier 2 (Domain Specialists): Mid-complexity tasks (document synthesis, code review, report generation) route to fine-tuned 70B-class models with structured tool integration.
- Tier 3 (Frontier Reasoning Engines): High-stakes, multi-hour challenges (regulatory audits, M&A due diligence, automated clinical trial analysis) trigger full Test-Time Compute with Monte Carlo reasoning trees and Process Reward Model verification.
SyncFlo AI Architectural Blueprint for Enterprises
At SyncFlo AI, we provide enterprise teams with plug-and-play autonomous agent infrastructure that seamlessly binds frontier reasoning models, Model Context Protocol (MCP) integrations, and native Computer-Using Agents.
7. Frequently Asked Questions (FAQ)
What makes 2026 autonomous AI fundamentally different from 2024 chatbots?
The distinction lies between static generation and dynamic reasoning. 2024 models operated on instantaneous next-token prediction, prone to compounding hallucinations over long workflows. 2026 systems utilize Test-Time Compute (TTC) and Process Reward Models (PRMs) to plan, verify intermediate steps, backtrack from dead ends, and visually operate computers and laboratory equipment.
Can Computer-Using Agents operate securely within enterprise firewalls?
Yes. Modern CUA deployments run inside zero-trust, isolated virtual desktop infrastructure (VDI) containers. Every simulated click and keypress is recorded to an immutable cryptographic audit log, and operations with high financial or security impact require human-in-the-loop authorization gates.
How does SyncFlo AI help businesses deploy these autonomous reasoning systems?
SyncFlo AI delivers enterprise-grade orchestration platforms that connect frontier reasoning models to your internal data warehouses, legacy ERPs, and workflow tools via Model Context Protocol (MCP) and secure Computer-Using Agent harnesses.