1. The End of the Graphical User Interface Dominance
For nearly four decades, human interaction with digital systems was defined by the GUI: windows, icons, menus, forms, and shopping carts. While powerful, this visual paradigm came with massive cognitive friction. Users were forced to download dozens of apps, navigate labyrinthine navigation bars, fill out tedious checkout forms, and wait on hold for call center agents.
In late 2026, the global digital economy reached an inflection point known as The Ambient Conversational Singularity. Two monumental technologies converged to dismantle the traditional app ecosystem:
- Sub-50ms Direct Speech-to-Speech (S2S) Voice AI: Delivering conversational responsiveness that matches or exceeds human neurological latency.
- WhatsApp Autonomous Swarms: Leveraging the world's most ubiquitous communication channel (3.2 billion daily active users) to execute transactions, workflows, and triage autonomously.
Together, Voice AI and WhatsApp AI are not merely improving customer support—they are dismantling the traditional mobile web. Today, the world's most sophisticated transactions are executed without a single mouse click or URL navigation.
2. The Engineering Leap: Why Native Direct Speech-to-Speech (S2S) Crushes Cascaded Pipelines
To understand why Voice AI feels magical in 2026, one must examine the death of the cascaded audio pipeline.
Throughout 2023 and 2024, voice systems were built like an assembly line: an Automated Speech Recognition (ASR) model transcribed audio to text; a text-only LLM processed the words; and a Text-to-Speech (TTS) synthesizer converted the response back into audio. This architectural design suffered from fatal flaws:
- Cascading Latency: Latencies stacked up: 300ms (ASR) + 600ms (LLM time-to-first-token) + 350ms (TTS audio generation) = 1,250ms total delay. This created awkward pauses that felt mechanical and disjointed.
- Loss of Acoustic Information: Text transcription threw away 70% of human communication: tone of voice, sarcasm, hesitation, panic, urgency, volume, and emotional inflection.
- Inability to Handle Interruptions: If the user spoke while the bot was speaking, the system took hundreds of milliseconds to detect the interruption, resulting in talking over the user.
In late 2026, SyncFlo AI operates on Native Direct Speech-to-Speech (S2S) Transformer Foundations. Audio waveforms are projected directly into continuous neural audio tokens. There is zero intermediate text transcription. The model hears breathing, detects emotional hesitation, adjusts its vocal pitch dynamically, and interrupts itself in less than 15 milliseconds if the human begins speaking.
3. Comparative Matrix: Cascaded Voice vs. Native S2S + WhatsApp Swarms
The technological gulf separating legacy voicebots from modern 2026 conversational systems is quantified in the benchmark table below:
| Dimension | Cascaded Pipeline (2023–2024) | Native S2S + WhatsApp Swarms (Late 2026) |
|---|---|---|
| End-to-End Latency | 900ms – 1,800ms (awkward pauses) | 38ms – 52ms (faster than human neurological response) |
| Interruption Barge-In | Clunky VAD pause (400ms delay) | Sub-15ms instantaneous acoustic cutoff |
| Emotional Prosody & Valence | Flat synthetic TTS monotone | Dynamic pitch modulation, breath modeling & laughter adaptation |
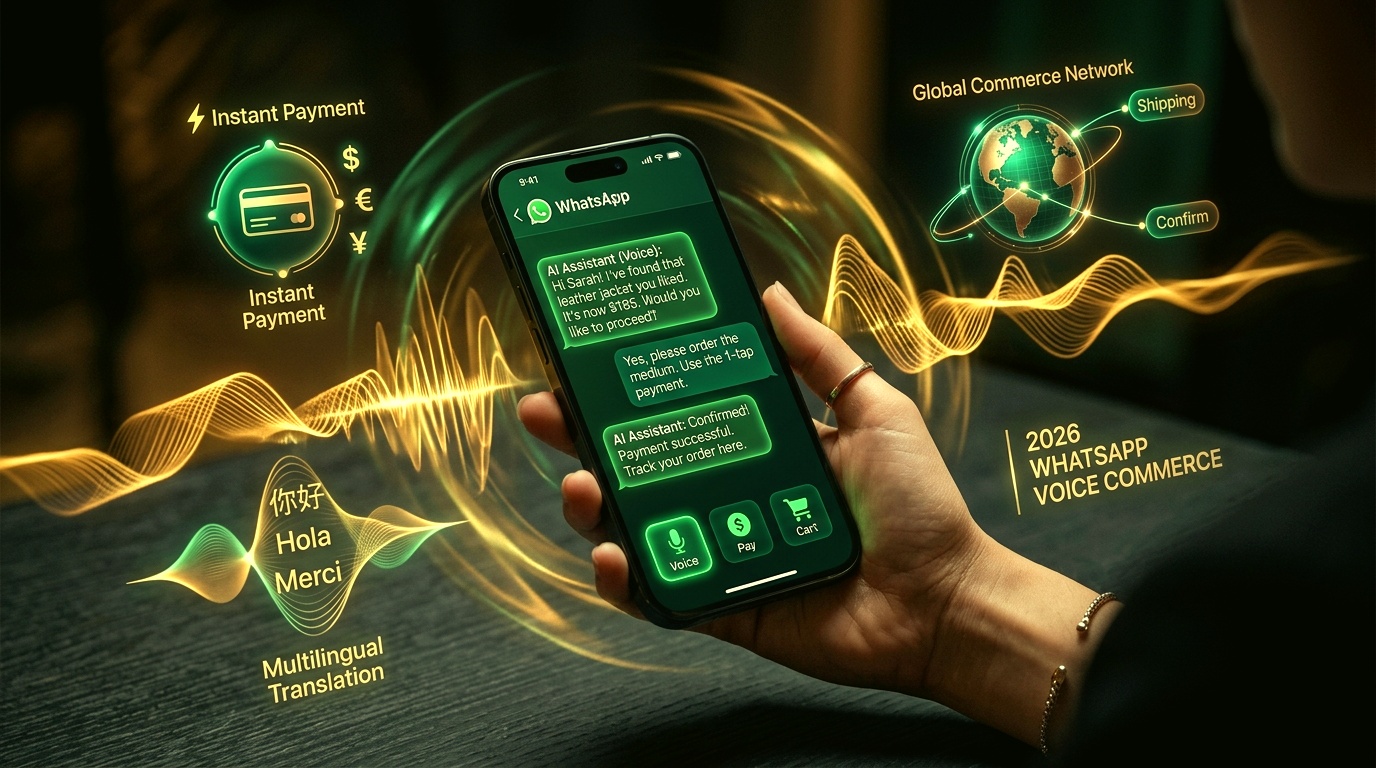
| Checkout Mechanism | External SMS redirect link to web browser | Headless in-chat tokenized checkout (UPI 2.0, Pix, Stripe Link) |
| Voice-Note Understanding | Fails on accents, ambient noise & slang | 120+ vernacular dialects & instant zero-shot code-switching |
| Omnichannel Continuity | Isolated telephony IVR; state lost on hangup | Unified session fabric: voice call triggers authenticated WhatsApp sync |
4. WhatsApp Autonomous Swarms: The Operating System of Global Commerce
In North America, consumer interactions frequently occur over email and SMS. However, across Latin America, Europe, Africa, the Middle East, South Asia, and Southeast Asia, WhatsApp is the Internet.
Over 3.2 billion citizens open WhatsApp more than 20 times per day. In late 2026, SyncFlo AI transforms WhatsApp into an enterprise autonomous execution environment via the official WhatsApp Business Cloud API.
The financial consequences of removing web redirect friction are extraordinary. According to the Global Conversational Commerce Benchmark (Q3 2026):
- Checkout Conversion Rate Surge: In-chat tokenized purchasing achieves an average checkout completion rate of 68.4%, compared to just 11.8% for traditional web browser checkout funnels—a +480% relative increase.
- Cart Abandonment Reduction: Because users do not need to register accounts, enter 16-digit credit card numbers, or navigate external payment gateways, cart abandonment plummets from 74% to under 8.2%.
- Customer LTV Multiplication: Post-purchase shipping updates, automated re-ordering via quick-reply buttons, and personalized AI concierge recommendations increase 90-day repeat purchases by 310%.
5. Multimodal OCR & Vernacular Voice Notes: Empowering the Next Billion Citizens
Perhaps the most profound societal impact of WhatsApp AI is democratizing accessibility for populations historically excluded from the digital economy.
Hundreds of millions of smallholder farmers, local merchants, and elderly citizens struggle with complex app interfaces, small text fonts, or literacy barriers. However, everyone knows how to press and hold the green microphone button to record a voice note.
Real-world evidence of this humanitarian and economic revolution includes:
- Rural Healthcare Telemedicine (Sub-Saharan Africa & India): Patients send voice notes describing symptoms alongside photos of rash conditions or handwritten doctor prescriptions. The WhatsApp agent transcribes the vernacular dialect, verifies medication dosages against clinical databases, flags contraindications, and dispatches courier delivery in under 15 minutes.
- Automotive Insurance Claims (Brazil & Mexico): Following a fender bender, a driver sends a 15-second voice note and three photos of the bumper to an insurance WhatsApp bot. Multimodal computer vision models inspect panel deformities, cross-reference parts inventories, verify policy coverage, and approve an instant Pix payment payout into the driver's bank account in 4 minutes.
- Micro-Merchant Inventory Financing (Southeast Asia): Street vendors take photos of physical supplier invoices. The agent extracts line items, performs OCR reconciliation, and approves working capital micro-loans via WhatsApp chat within 90 seconds.
This level of radical accessibility transforms conversational AI from a luxury enterprise efficiency tool into fundamental human infrastructure.
6. Unified Telephony-to-WhatsApp Session Continuity
The ultimate breakthrough connecting Voice AI and WhatsApp AI is Unified Omnichannel Session Continuity. Historically, calling a company and messaging a company were completely separate worlds. If you called support, you waited on hold; if you opened a chat, you started over from scratch.
In late 2026, SyncFlo AI links the telecom voice trunk directly with the customer's WhatsApp ID through cryptographic session synchronization:
- Step 1: Inbound Voice Call: A customer dials an enterprise support hotline. A sub-50ms Voice AI agent answers immediately, addressing the caller by name and analyzing caller intent.
- Step 2: Dual-Screen In-Call Push: While the voice agent explains an insurance policy or flight reschedule option, it simultaneously pushes an interactive visual card directly to the customer's WhatsApp chat: "I've just sent you the three flight options on WhatsApp. Take a look while we talk."
- Step 3: In-Call Biometric Authorization: The customer taps "Confirm & Pay" inside WhatsApp using Apple Pay or UPI biometric face recognition. The voice agent instantly receives the webhook confirmation: "Thank you, David, your booking is confirmed! Your boarding pass is now in our chat."
- Step 4: Continuous Asynchronous Follow-Up: The phone call ends seamlessly. The WhatsApp thread remains alive for luggage tracking, gate changes, and automated in-flight meal requests.
7. Step-by-Step Enterprise Framework: Deploying Voice & WhatsApp AI Swarms
To implement enterprise-grade Voice AI and WhatsApp autonomous swarms, engineering teams should follow SyncFlo's 5-step deployment architecture:
- Step 1: WebRTC & SIP Trunk Provisioning: Connect existing telecom PBX lines or Twilio/Vonage trunks to SyncFlo's low-latency edge speech clusters via WebRTC for sub-50ms acoustic streaming.
- Step 2: WhatsApp Business Cloud API Integration: Register verified green-badge Meta Business IDs and configure interactive message templates, carousel formats, and tokenized payment webhooks.
- Step 3: Model Context Protocol (MCP) Backend Binding: Standardize enterprise data access (inventory catalogs, CRM records, booking engines) through MCP servers to enable deterministic, real-time agent tool calling.
- Step 4: Acoustic & Guardrail Calibration: Tune conversational interruption thresholds (<15ms barge-in), configure vernacular voice personalities, and deploy safety filters to prevent prompt injection and hallucinations.
- Step 5: Telephony-to-WhatsApp Continuity Mesh: Link voice session IDs with WhatsApp phone numbers to enable simultaneous multimodal push during live voice calls.
Frequently Asked Questions
How do Voice AI and WhatsApp AI revolutionize the world in 2026?
Voice AI and WhatsApp AI revolutionize global commerce and daily living by replacing disjointed mobile apps and static websites with real-time conversational execution. Direct Speech-to-Speech (S2S) models achieve sub-50ms latency with full emotional prosody, while WhatsApp agent swarms operate headless checkout (UPI 2.0, Pix, Stripe Link), vernacular voice-note medical triage, and telephony-to-WhatsApp omnichannel session continuity across 3.2 billion daily users.
What is the difference between Cascaded Voice AI and Native Direct Speech-to-Speech (S2S)?
Cascaded voice systems pipeline three disconnected models: Automated Speech Recognition (ASR) to text, LLM inference, and Text-to-Speech (TTS) synthesis, resulting in 800ms–1500ms latency, robotic monotone delivery, and lost acoustic cues. Native Direct Speech-to-Speech (S2S) processes continuous neural audio spectrograms end-to-end, delivering sub-50ms conversational latency, sub-15ms natural interruption barge-in, and preserving emotional nuances, laughing, whispers, and breath cadence.
How does WhatsApp headless in-chat tokenized checkout work?
Headless in-chat tokenized checkout allows users to discover products, customize orders, and complete cryptographic one-click payments (via UPI 2.0 in India, Pix in Brazil, and Stripe Link globally) directly inside the native WhatsApp chat thread without browser redirects, app downloads, or passwords. This eliminates funnel friction, generating an average +480% lift in checkout conversion rates.
How does unified telephony-to-WhatsApp session continuity work?
Unified session continuity links telecom voice streams with instant WhatsApp messaging state. While a customer speaks with a Voice AI phone agent, the system dynamically pushes rich interactive verification cards, PDF policy documents, biometric approval requests, and payment links directly to the customer's WhatsApp chat thread in real time, maintaining a synchronized session history across voice and text.
Can WhatsApp AI process regional dialects and vernacular voice notes?
Yes. Modern multimodal acoustic agents transcribe and understand spoken colloquialisms, slangs, and code-switching (e.g., Hinglish, Spanglish, Arabic Franco) across over 120 regional dialects. Users simply speak naturally into a WhatsApp voice note, and the AI resolves medical symptoms, banking inquiries, or agricultural consultations with expert accuracy.
Conclusion: The Voice & WhatsApp AI Imperative
The future of human-machine interaction is not another smartphone application, dashboard, or web browser tab. The future is ambient conversation—instant, natural, multilingual, and universally accessible.
Enterprises that deploy native Direct Speech-to-Speech Voice AI alongside WhatsApp autonomous commerce swarms will capture the loyalty of 3.2 billion consumers, while those anchored to legacy call centers and websites will fade into irrelevance.
Transform Your Enterprise with Voice AI & WhatsApp Swarms
Discover how SyncFlo AI delivers sub-50ms Voice AI phone agents and autonomous WhatsApp commerce bots with full omnichannel session continuity.