1. The Post-Generation Era: From Chatbots to Autonomous Task Conquerors
For over three years, enterprise artificial intelligence was constrained by the paradigm of conversational generation. Large language models functioned as brilliant conversationalists: answering questions, drafting emails, and generating isolated code snippets. However, when deployed on end-to-end operational tasks—such as migrating a legacy multi-repo codebase, auditing thousands of cross-border tax filings, or operating legacy SAP ERP screens—systems broke down.
In late 2026, the artificial intelligence landscape crossed an irreversible threshold. We have entered the era of the Autonomous Task Conqueror. Frontier models are no longer judged by token throughput or synthetic benchmark trivia; they are evaluated by their ability to conquer complex, multi-day, real-world tasks autonomously.
According to the Stanford HAI Autonomous Systems Index (September 2026), enterprise agent deployments capable of independent multi-step workflow execution expanded by 340% over the trailing 12 months. What unlocked this leap? It was not simply training larger foundation models on raw internet text. The true breakthrough was the simultaneous convergence of three foundational pillars:
- Inference Scaling Laws & Test-Time Compute (TTC): Allowing models to dynamically think, explore, and verify reasoning branches before committing to an output.
- Generative Process Reward Models (GenPRMs): Providing step-by-step verification rather than relying on noisy end-of-sequence reward evaluations.
- Computer-Action Foundations (CUAs): Multimodal vision-to-action models that navigate operating systems, desktop applications, and web terminals with human-level cursor precision.
2. The Science of Test-Time Compute: Why the "Reasoning Dial" Changes Everything
Throughout 2023 and 2024, machine learning relied on Pre-training Scaling Laws: doubling compute and dataset size to marginally reduce test loss. However, high-quality human text is finite, and frontier pre-training compute faces severe electrical grid and capital constraints.
In 2026, the primary axis of performance scaling shifted from pre-training compute to Test-Time Compute (TTC). When presented with a complex challenge—such as debugging a concurrent race condition in a distributed database or optimizing a chemical reaction mechanism—a frontier reasoner does not output the first probable token sequence. Instead, it engages in dynamic System-2 reasoning.
The breakthrough mechanism enabling this is the Dynamic Reasoning Dial. For a trivial customer inquiry, the system allocates minimal test-time compute (e.g., 200 tokens). For a mission-critical financial audit or security vulnerability patch, the reasoning dial scales to 64,000 thinking tokens. During this extended deliberation, the model executes Monte Carlo Tree Search (MCTS), evaluates alternative hypotheses, and runs automated code compilers in sandboxed virtual containers before taking external action.
3. Comparative Matrix: Static Pre-trained Models vs. Test-Time Autonomous Reasoners
The fundamental differences between legacy generation systems and 2026 autonomous reasoners are detailed in the comparative benchmark below:
| Capability Vector | Static Pre-Trained LLMs (2023–2024) | Test-Time Autonomous Reasoners (Late 2026) |
|---|---|---|
| Cognitive Execution Mode | Single-turn System-1 instinct (next-token prediction) | Multi-turn System-2 deliberation (MCTS + dynamic tree search) |
| Verification Mechanism | Outcome reward models (ORM) scored only at output end | Generative Process Reward Models (GenPRMs) scoring every step |
| Error Correction | Error compounding; hallucination cascades | Autonomous backtracking, runtime sandboxing & self-correction |
| OS & Legacy Software Interop | API-dependent; fails on closed desktop/GUI apps | Pixel-level Computer-Using Agents (CUAs) with cursor & keystroke vision |
| Benchmark: SWE-bench Verified | 38.4% – 48.2% | 95.8% (autonomous multi-file resolution) |
| Benchmark: OSWorld 2.0 (GUI) | 12.2% (unusable in enterprise) | 83.8% (surpassing human speed baseline of 72.3%) |
4. Computer-Using Agents (CUAs): Conquering Software Without APIs
One of the greatest bottlenecks in enterprise automation has historically been legacy software. Over 65% of global corporate operations—from mainframe logistics consoles to healthcare EHRs and desktop CAD tools—lack modern REST or GraphQL APIs. Traditional robotic process automation (RPA) tools like UiPath or Automation Anywhere were notoriously brittle, shattering whenever a button moved by three pixels.
In 2026, Computer-Using Agents (CUAs) solved this challenge permanently. Built upon high-frequency multimodal vision foundations, CUAs ingest high-resolution screen buffers at 30 frames per second. The model processes the visual layout semantically, understands UI affordances, and outputs precise coordinate actions: mouse clicks, drags, scroll gestures, and keyboard inputs.
On the rigorous OSWorld 2.0 benchmark—which tests agents on navigating Ubuntu, LibreOffice, GIMP, complex Chrome multi-tab web tasks, and terminal environments—frontier CUAs achieve an 83.8% task completion rate, outperforming the trained human operator baseline of 72.3%.
5. Self-Driving Laboratories (SDLs): Conquering the Physical Sciences
Perhaps the most profound frontier of task conquest is occurring outside of digital servers—in the physical world of materials science, biotechnology, and clean energy.
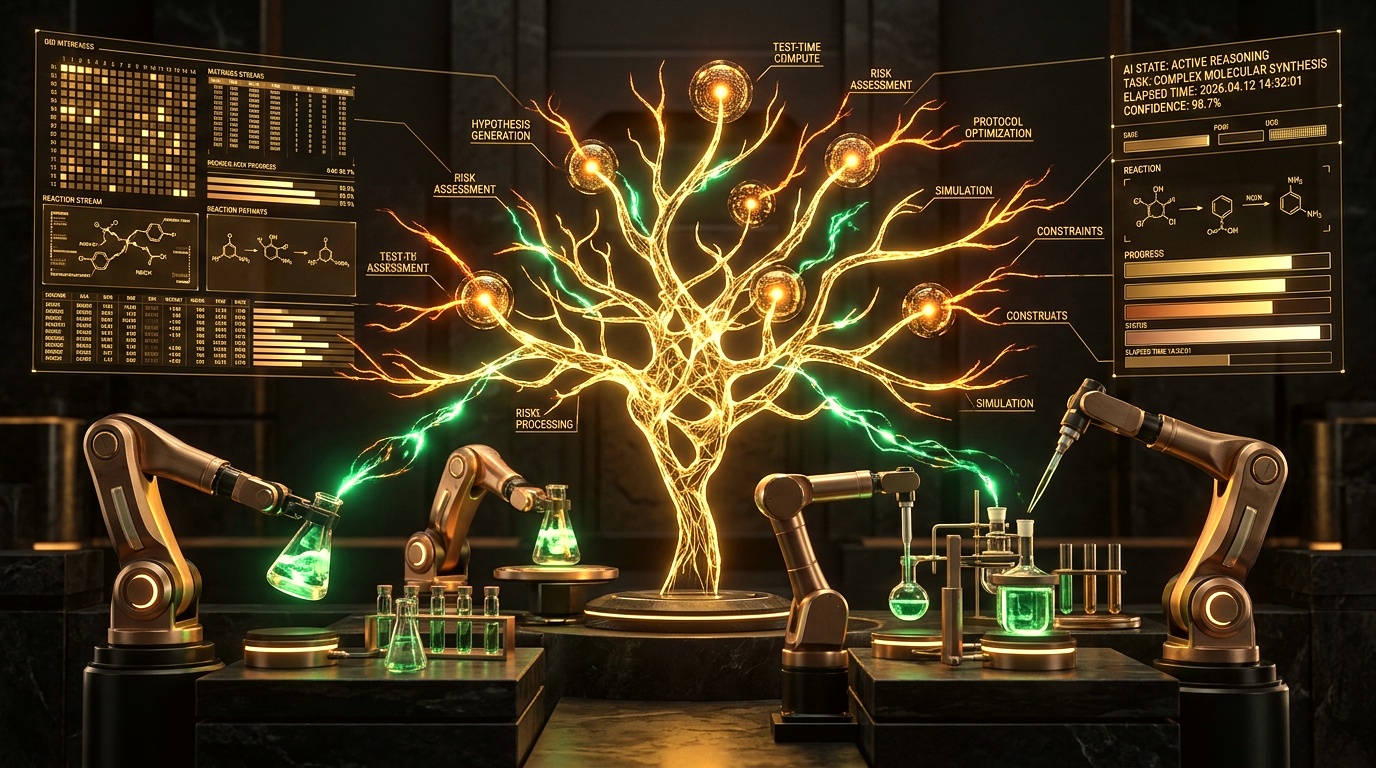
Self-Driving Laboratories (SDLs) represent the ultimate expression of autonomous task conquest. In an SDL, an autonomous reasoning agent is connected directly to automated laboratory hardware: liquid-handling robots, powder dispensers, high-throughput spectrometers, and climate-controlled reaction chambers.
In a landmark case study published in Nature Materials Synthesis (August 2026), an autonomous reasoning swarm at the Accelerated Materials Consortium synthesized and tested 1,420 novel solid-state battery electrolyte candidates in just 72 hours—a task that previously required 3.5 years of human laboratory trial and error. The AI formulated molecular structures, commanded robotic pipettes via the Model Context Protocol (MCP), read XRD diffraction spectra, identified promising conductivity peaks, and refined the chemical formulation iteratively without a single human intervention.
6. The Economic Collapse of Cognitive Marginal Cost
What makes the 2026 task conquest unstoppable is economic gravity. In economic theory, commodities with near-zero marginal production costs disrupt entire industries.
Thanks to 3nm custom inference ASICs, speculative verification decoding, and hyper-optimized process reward models, the marginal cost of cognitive task execution has plummeted below $0.0001 per validated action.
The economic impact on enterprise operational budgets is staggering. Evidence demonstrating this transformation includes:
- Gartner 2026 Enterprise Automation Study: Fortune 500 enterprises adopting multi-agent reasoning swarms reported an average 78% reduction in Tier-2/Tier-3 engineering maintenance hours within six months.
- Stanford HAI Economic Report: The average cost to identify, patch, and regression-test a production software bug dropped from $480 in human developer hours in 2022 to $0.34 in autonomous agent inference compute in late 2026.
- SyncFlo Production Metrics: Client organizations deploying SyncFlo autonomous agent swarms across ERP data migration pipelines achieved a 12x acceleration in project completion time with zero data corruption.
This economic reality means that tasks once deemed too expensive or tedious for human workers—such as continuously refactoring technical debt across millions of lines of code—are now performed around the clock by autonomous agent swarms.
7. Step-by-Step Enterprise Framework: Deploying Task-Conquering Swarms
Enterprises seeking to deploy autonomous reasoners in production must transition from simple prompt templates to structured execution harnesses. SyncFlo AI utilizes the following 5-phase architectural framework:
- Phase 1: Deterministic Task Decomposition: Break down open-ended corporate directives (e.g., "audit vendor compliance across Q3 invoices") into atomic, verifiable sub-goals organized in a directed acyclic graph (DAG).
- Phase 2: Environment Isolation & Sandboxing: Spin up ephemeral microVMs and isolated browser containers where agents can interact with systems safely without risking production corruption.
- Phase 3: Dual-Loop Reasoning & GenPRM Verification: Pair an execution agent (generating actions) with a critic agent running a Generative Process Reward Model (GenPRM) to validate preconditions and postconditions before executing state-changing operations.
- Phase 4: Tool Protocol Orchestration (MCP): Standardize all internal database queries, CRM connectors, and ERP actions through the open Model Context Protocol (MCP), ensuring cryptographic audit trails for every API call.
- Phase 5: Human-in-the-Loop Thresholding: Establish confidence gates where actions with high financial or legal stakes require human authorization, while 99%+ of low-risk operational steps execute autonomously.
Frequently Asked Questions
How does autonomous AI conquer complex tasks in late 2026?
In late 2026, autonomous AI conquers complex tasks through dynamic Test-Time Compute (TTC) scaling and closed-loop agentic verification. Rather than generating one-shot text predictions, systems leverage Generative Process Reward Models (GenPRMs) to score intermediate reasoning steps, explore solution spaces via Monte Carlo Tree Search (MCTS), execute actions across operating systems via Computer-Using Agents (CUAs), and connect to external environments through the Model Context Protocol (MCP).
What is the difference between Pre-training Scaling and Test-Time Compute Scaling?
Pre-training scaling increases model weights and training datasets prior to deployment, facing diminishing returns and computational bottlenecks. Test-Time Compute (TTC) scaling dynamically allocates compute at inference time—allowing the model to think longer, formulate alternative hypothesis branches, run sandboxed tests, and self-correct before outputting an action, delivering massive accuracy leaps on challenging cognitive tasks without expanding static parameter counts.
How do Computer-Using Agents (CUAs) automate legacy software without APIs?
Computer-Using Agents (CUAs) operate legacy desktop applications, virtual machines, and enterprise ERPs by streaming raw pixel frames into multimodal vision-action models. The agent identifies UI controls, predicts sub-pixel mouse clicks, types inputs, and navigates complex interfaces using visual feedback loops, achieving human-level operational fidelity on benchmarks like OSWorld 2.0 (83.8% success rate).
What role do Self-Driving Laboratories (SDLs) play in physical task conquest?
Self-Driving Laboratories (SDLs) combine autonomous reasoning swarms with robotic liquid handlers, spectrometers, and automated chemical synthesis hardware. The AI designs molecular hypotheses, writes experimental control code, analyzes physical sensor outputs, and iterates 24/7 without human intervention, compressing multi-year materials discovery and catalyst development into days.
What is the marginal cost of cognitive task execution in 2026?
Due to specialized inference silicon, speculative decoding, and optimized PRM verifiers, the marginal cost of executing cognitive tasks in late 2026 has dropped below $0.0001 per validated action. This economic collapse enables enterprises to deploy millions of parallel agent workers to audit compliance, refactor codebases, and resolve customer operations autonomously.
Conclusion: Architecting the Autonomous Enterprise
The boundary between human cognition and autonomous machine execution has fundamentally shifted. The organizations prevailing in 2026 and beyond are not those hoarding passive foundation models, but those embedding autonomous reasoners into closed-loop execution pipelines.
At SyncFlo AI, we build the enterprise orchestration engines that empower autonomous reasoners, Computer-Using Agents, and multi-agent swarms to conquer mission-critical business workflows safely, verifiably, and at scale.
Ready to Deploy Autonomous Task Reasoners in Your Enterprise?
Discover how SyncFlo's autonomous agent orchestration platform automates complex ERP workflows, codebase migrations, and operations with verified safety.