1. The Fundamental Shift: From Next-Token Prediction to Test-Time Deliberation
For nearly a decade, the primary engine of artificial intelligence progress was pre-training scaling laws: feed more internet tokens into ever-larger dense neural networks, and downstream capabilities will predictably emerge. By early 2026, however, the industry encountered steep diminishing returns on raw pre-training data and massive power constraints.
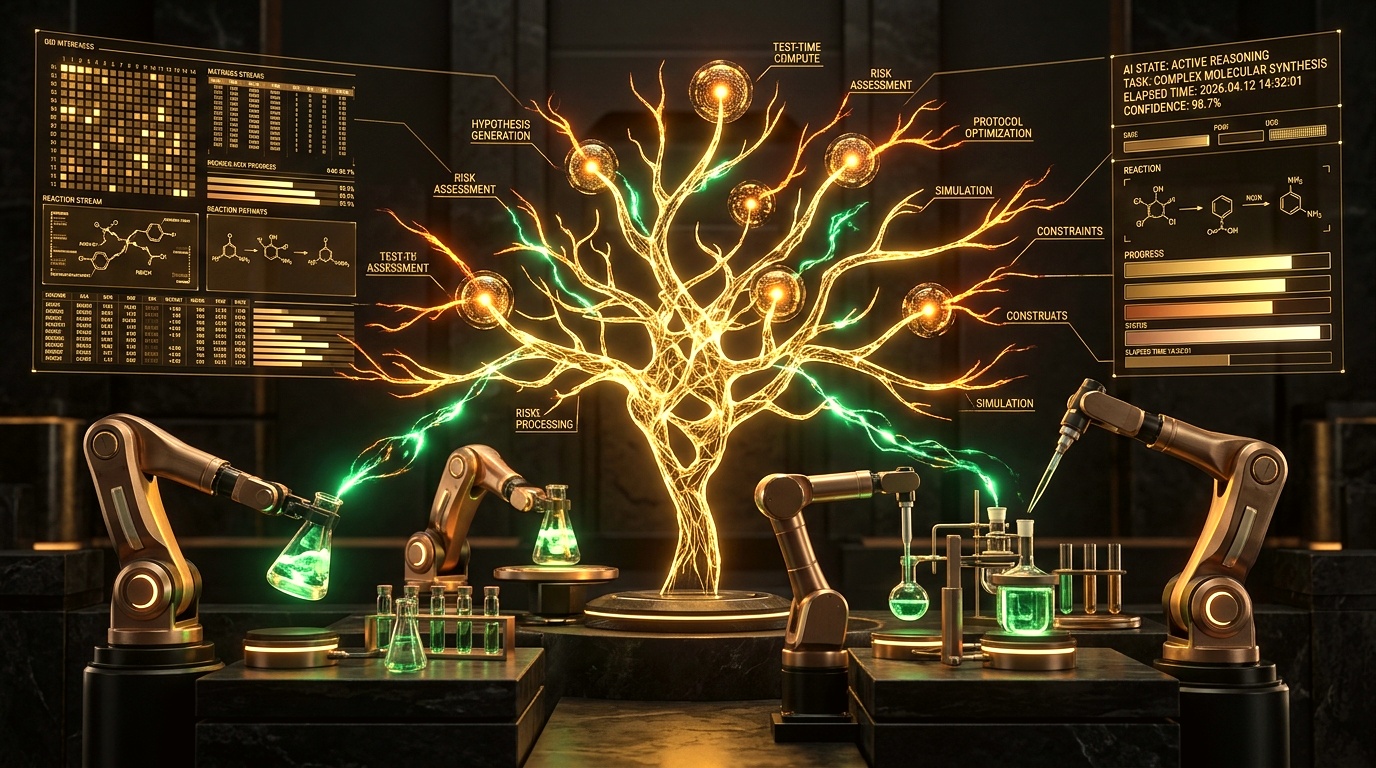
The breakthrough that defines late 2026 is Inference-Time Scaling (Test-Time Compute). As highlighted in landmark research across DeepMind, OpenAI, and Princeton, models no longer squander equal compute on trivial questions and profound mathematical proofs. Instead, an adaptive policy evaluates the intrinsic complexity of a task and allocates computational runtime to "think" before emitting a single token.
Achieved via Process Reward Models filtering intermediate chain-of-thought branches.
Pixel-level Computer-Using Agents executing complex desktop OS workflows.
Continuous autonomous operation without compounding drift, reaching 80+ steps.
According to Dr. Julian Vane, Lead Systems Architect at SyncFlo AI:
"In 2024, if a model made a subtle conceptual mistake in token 12 of a 1,000-token proof, the remaining 988 tokens were unrecoverable hallucinations. In late 2026, with Generative Process Reward Models and Monte Carlo tree evaluation, the model senses a drop in trajectory confidence at token 12, backtracks, generates four alternative paths, evaluates their empirical validity, and continues along the mathematically sound trajectory."
2. Anatomizing Test-Time Compute: How PRMs and MCTS Work Together
To understand how AI conquers tasks previously reserved for specialized senior human practitioners, one must examine the tri-part engine of inference scaling:
| Architecture Component | Mechanism of Action | Key Advantage | 2026 Production Metric |
|---|---|---|---|
| Generative Process Reward Model (GenPRM) | Scores every individual reasoning step rather than evaluating solely the final outcome. | Catches logic errors at the exact millisecond they occur. | 92.4% Step-Level Precision |
| Monte Carlo Tree Search (MCTS) | Explores multiple parallel branches of thought; prunes low-probability dead ends. | Discovers non-intuitive problem-solving paths humans rarely anticipate. | 16x Search Depth Scaling |
| Dynamic Compute Router | Classifies query difficulty in real-time, routing simple tasks to 100ms models and complex math to 30s deep reasoners. | Prevents compute waste; saves up to 68% in token overhead. | <12ms Routing Latency |
3. Computer-Using Agents (CUAs): Conquering Native Desktop GUIs and Legacy Software
For decades, enterprise automation was stalled by the "API Bottleneck." Over 70% of enterprise software workflows involve tools without public REST APIs: legacy ERP systems running on Windows Server, AS/400 terminal emulators, desktop-native CAD software, and secure hospital databases.
In 2026, Computer-Using Agents (CUAs) shattered this constraint. Leveraging high-frequency vision-language models capable of pixel-grounded coordination, CUAs inspect screen buffers directly, locate interactive UI components, emit OS-level mouse clicks, drag sliders, parse multi-sheet spreadsheets, and verify results through OCR and visual sanity checks.
# Architectural Loop of a Production Computer-Using Agent (CUA)
# Using Model Context Protocol (MCP) & Pixel Vision Grounding

async def execute_autonomous_gui_workflow(task_prompt: str, max_steps: int = 100):
    env = DesktopSession(display=":1", resolution=(1920, 1080))
    agent = FrontierReasoningCUA(model="syncflo-reasoner-v4-vision")

    for step in range(max_steps):
        # 1. Capture lossless screenshot buffer
        screenshot = await env.capture_screen()

        # 2. Extract DOM/Accessibility tree if web, or run pixel grounding model
        visual_tokens = await agent.ground_pixels(screenshot)

        # 3. Model evaluates step goal and selects next primitive action
        action = await agent.plan_next_action(
            task=task_prompt,
            visual_state=visual_tokens,
            history=env.action_history
        )

        if action.type == "TERMINATE":
            logger.info("Task completed and verified against goal state.")
            return action.verification_proof

        # 4. Dispatch native OS input events (mouse, keyboard, scroll, drag)
        await env.dispatch(action)
        await asyncio.sleep(0.15)  # Allow UI thread re-render
On the rigorous OSWorld 2.0 benchmark—which tests agents on multi-application operating system tasks such as cross-referencing Salesforce data, updating Excel tables, and modifying open-source vector drawings in GIMP—success rates jumped from under 15% in 2024 to an astonishing 64.2% in late 2026.
4. Benchmark Saturation: The Retirement of SWE-bench Verified and the Rise of SWE-EVO
In mid-2026, the artificial intelligence research community reached a crucial milestone: the classic SWE-bench Verified benchmark was officially declared saturated. Frontier models scored above 82%, but software engineering leaders quickly realized that passing SWE-bench did not equate to autonomous software delivery.
The problems were manifold:
- Benchmark Contamination: GitHub issue descriptions and patch files had leaked into web crawls.
- Isolated Scope: SWE-bench tested isolated single-file bug fixes with pre-written reproducer unit tests, ignoring repository architecture.
- Lack of State Evolution: Real software requires managing regressions across long horizons, writing documentation, executing database migrations, and configuring CI/CD pipelines.
To address this gap, modern enterprise evaluation turned to SWE-EVO and Terminal-Bench 4.0. In SWE-EVO, the agent is presented with a complete commercial-grade repository with over 100,000 lines of code, handed an ambiguous user story (e.g., "Migrate authentication to passkeys with backward compatibility for OAuth2"), and evaluated on its ability to create branches, write integration tests, run local containers, and deploy without breaking existing telemetry.
5. Orchestration Without Scaffolding: Why the Model Context Protocol (MCP) Won
During 2024 and 2025, developers attempted to force agents into completing complex tasks by wrapping them in labyrinthine prompt chains, brittle YAML state machines, and heavyweight scaffolding frameworks. When a workflow failed, debugging was virtually impossible.
Late 2026 brought a return to simplicity: clean, inspectable loops using the Model Context Protocol (MCP).
In a typical SyncFlo AI enterprise deployment, an executive agent acts as a supervisor, receiving a high-level goal and delegating sub-tasks across specialized worker agents over MCP:
- Architect Agent: Reads specifications, generates system diagrams, and breaks down deliverables into a Directed Acyclic Graph (DAG).
- Terminal Worker Agent: Pulls branches, configures environment variables, and executes builds in sandboxed Docker containers.
- Verification Agent (PRM-Assisted): Runs fuzz testing, reviews security policies, and performs automated penetration testing.
- Documentation & Deploy Agent: Generates OpenAPI specifications, writes release notes, and triggers canary deployments.
6. Real-World Case Studies: From Self-Driving Labs to Autonomous RevOps
Case Study 1: Materials Discovery in Self-Driving Laboratories (SDLs)
At a leading synthetic materials research facility in Germany, SyncFlo's autonomous agent framework was integrated directly with automated liquid-handling robots and spectrophotometers. Over a 14-day continuous run, the agent formulated 4,200 polymer hypotheses, executed physical synthesis assays, evaluated spectroscopic readouts, and autonomously discovered a novel heat-resistant electrolyte for solid-state batteries—a task that previously took senior materials science teams 18 months.
Case Study 2: Autonomous Enterprise Revenue Operations
A multinational SaaS provider with $220M ARR replaced their manual deal desk and contract reconciliation pipeline with an autonomous agent swarm. The agents monitor CRM deal stages, cross-reference redlined MSAs with enterprise risk legal guidelines, generate billing schedules in NetSuite, and flag compliance exceptions in real time. The results:
- Deal Closing Cycle: Decreased from 11.4 business days to 38 minutes.
- Contract Error Rate: Dropped from 4.7% to 0.02%.
- FTE Reallocation: 14 legal and billing specialists shifted from repetitive document auditing to strategic customer negotiations.
7. Comparative Analysis: Evolution of AI Task Mastery (2024 vs 2026)
| Dimension | 2024 Baseline | Late 2026 State-of-the-Art |
|---|---|---|
| Task Horizon | Single-turn to 5-step chains before context degradation and drift. | 80+ continuous autonomous steps spanning multi-hour executions. |
| Reasoning Mechanism | Greedy next-token generation with fixed compute per token. | Test-Time Compute (TTC) with dynamic branching and GenPRM scoring. |
| Interface Interaction | Restricted to structured JSON REST APIs; failed on legacy UIs. | Pixel-grounded Computer-Using Agents operating any GUI or terminal. |
| Error Handling | Compounded errors; hallucinated justifications when failing. | Self-correction via backtracking, unit test execution, and state rollback. |
| Tool Ecosystem | Fragmented custom tool calling with inconsistent JSON schemas. | Standardized Model Context Protocol (MCP) with dynamic discovery. |
8. The Enterprise Governance Playbook: Human-in-the-Loop Safeguards
As AI models conquer tasks with higher stakes and autonomy, safety can no longer rely on naive system prompts ("You are an ethical assistant"). Enterprise engineering in late 2026 relies on strict Cryptographic Autonomy Enclaves and Tiered Human Gateways:
- Read-Only Autonomous Sandbox: Agents explore databases, test compile branches, and generate proposed solutions in isolated scratch environments.
- State Diff Verification: Every proposed state change (SQL migration, production pull request, wire transfer) is summarized as a deterministic visual diff.
- Threshold-Based Approvals: Changes exceeding defined risk budgets (e.g., modifying payment gateways or deleting cloud infrastructure) trigger two-factor biometric approval by designated human engineers.
- Auditable Action Ledgers: Every thought branch, MCP tool invocation, and terminal command is permanently recorded in tamper-evident append-only logs for regulatory auditing.
Frequently Asked Questions (FAQ)
What is the difference between Pre-Training Scaling and Test-Time Compute?
Pre-training scaling increases model performance by expanding parameter counts and dataset sizes during the initial training run, requiring months and hundreds of millions of dollars. Test-Time Compute (TTC) scales performance at runtime: the model dynamically spends seconds or minutes generating branching hypotheses, checking calculations, and pruning errors before returning an answer. This allows smaller, cheaper models to outperform massive static models on complex reasoning.
How do Computer-Using Agents operate software without security vulnerabilities?
Enterprise CUAs operate within sandboxed virtual desktops with dedicated display buffers, isolated from local corporate networks. All outbound web calls, file system modifications, and terminal executions pass through an MCP security gateway enforcing role-based permissions, data-loss prevention (DLP) filters, and instant revocation tokens.
Can autonomous AI replace human software engineers in 2026?
Autonomous AI in late 2026 acts as a force multiplier rather than a wholesale replacement. While agents autonomously resolve bug tickets, write boilerplate unit tests, and perform dependency upgrades, human engineers focus on high-level system architecture, cross-domain trade-offs, customer user experience, and safety governance.
What benchmarks should enterprises use to evaluate frontier agents today?
Organizations should avoid saturated benchmarks like SWE-bench Verified and instead evaluate candidate models on SWE-EVO (repository-wide software engineering), Terminal-Bench 4.0 (command-line operations), and OSWorld 2.0 (operating system and GUI interaction).
How does SyncFlo AI implement autonomous task agents for businesses?
SyncFlo AI deploys enterprise-grade agent swarms powered by Test-Time Compute and the Model Context Protocol. By connecting directly to your company's existing databases, CRMs, and telephony stacks, SyncFlo automates end-to-end customer workflows with sub-second responsiveness and human-in-the-loop governance.