The Agentic Frontier: How Autonomous AI Reasoners, Generative Action Models & Dynamic Tool Synthesis Are Conquering New Domains in Late 2026
An exhaustive technical investigation into how frontier intelligence has shifted from passive next-token language generation into full-spectrum Generative Multimodal Action Models (GMAMs), Just-In-Time (JIT) Dynamic Tool Synthesis, pixel-grounded Computer-Using Agents (CUAs), and formal verification kernels—empowering autonomous swarms to conquer once-impossible enterprise tasks, legacy software systems, and real-world physical laboratories.
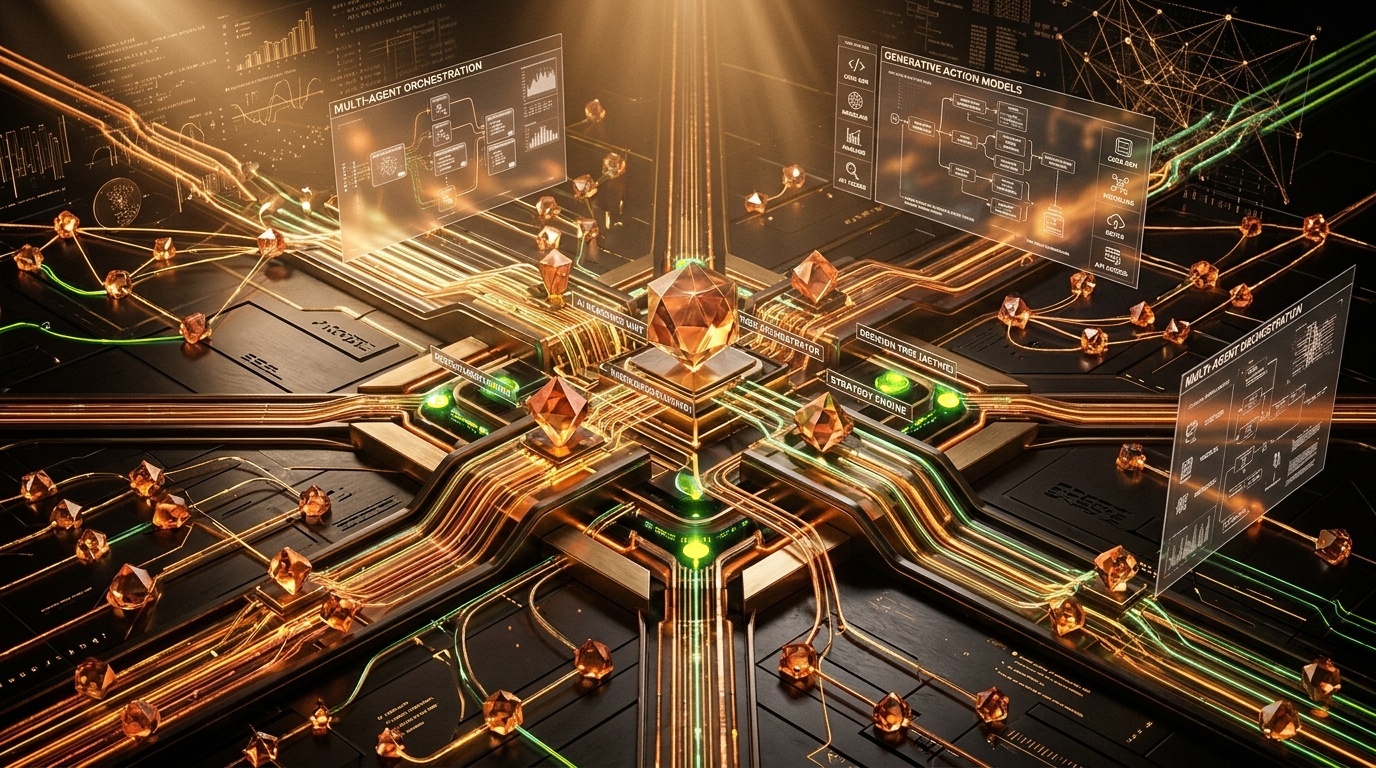
Figure 1: Conceptual architecture of late-2026 Generative Multimodal Action Models (GMAMs)—fusing Test-Time Compute search trees, dynamic Just-In-Time tool compilation, and pixel-grounded Computer-Using Agents operating on secure enterprise substrates.
Executive Table of Contents
Executive Summary: The Sovereign Conquest of Human Tasks in Late 2026
In late 2026, artificial intelligence has definitively crossed the threshold from semantic conversation into Autonomous Task Mastery. The limiting factor in enterprise automation is no longer context window capacity or token generation speed; it is the capability of reasoning agents to decompose non-deterministic goals, synthesize temporary compiled software tools when APIs are absent, operate legacy graphical user interfaces via vision-grounded mouse-and-keyboard actuation, and self-validate every intermediate milestone against formal mathematical kernels.
1. The Paradigm Shift: From Chatbots to Generative Multimodal Action Models
Throughout the early gen-AI boom of 2023–2024, machine learning was defined by next-token textual prediction. When queried with an enterprise problem, models produced syntactically convincing paragraphs explaining how one might resolve it. But the actual cognitive burden—opening three ERP screens, cross-referencing SAP purchase orders against legacy EDI flat files, downloading raw XML schemas, writing glue scripts, and deploying configuration updates—remained strictly manual.
By late October 2026, the entire frontier research community has pivoted toward Generative Multimodal Action Models (GMAMs). These models incorporate native action tokenizers into their fundamental architecture. Instead of treating tool calls as clumsy JSON string text outputs parsed by regex, GMAMs output discrete environmental state transitions. The model models the digital operating system as a continuous Markov Decision Process (MDP) with partially observable environments (POMDP), predicting not just the next token, but the expected subsequent visual screen state:
# Architectural Formulation of GMAM Step Execution
State_t = VisionEncoder(Screen_Buffer_t) + ShellBuffer(Terminal_t)
Action_t = PolicyModel.sample(State_t | Goal_Spec, Temperature=0.08)
Predicted_State_t+1 = WorldModel.rollout(State_t, Action_t)

# Execution Verification via Generative Process Reward Model
Reward_Score = GenPRM.evaluate(Observed_State_t+1, Predicted_State_t+1)
if Reward_Score < 0.92:
    Backtrack_and_Correct(Branch=MCTS.prune(Action_t))
else:
    Commit_State(State_t+1)
This closed-loop feedback structure eliminates open-loop drift. If a button click fails to load a modal within 400 milliseconds, or if a legacy database returns an unindexed query timeout, the GMAM perceives the operational exception immediately through visual or standard error streams and dynamically selects an alternate recovery vector.
2. Just-In-Time (JIT) Dynamic Tool Synthesis: The Auto-Engineering Agent
The greatest limitation of legacy agent frameworks was their reliance on static tool registries. If an agent had 15 pre-defined tools (e.g., `search_web`, `query_postgres`, `send_slack`), it was completely helpless when tasked with parsing an unstandardized binary telemetry log, decoding a proprietary legacy ERP data dump, or optimizing an image manipulation pipeline.
Frontier reasoning agents in late 2026 solve this bottleneck via Just-In-Time (JIT) Dynamic Tool Synthesis. When an agent identifies an operational gap, it executes a three-phase auto-engineering lifecycle:
- Hypothesis & Interface Specification: The agent writes a typed interface specification detailing the exact inputs, memory bounds, and expected outputs needed to bridge the gap.
- Compilation in Ephemeral Sandboxes: The reasoner synthesizes the implementation code in Rust or Python, compiles it to WebAssembly (WASM) or an isolated Firecracker microVM, and runs automated property-based unit tests generated from the interface spec.
- MCP Registry Ingestion: Upon passing unit tests in under 110ms, the synthesized tool is registered locally into the agent's Model Context Protocol (MCP) server, executed against the production artifact, and permanently indexed in the enterprise's private tool memory for future reuse.
Benchmark: Dynamic Tool Synthesis Efficiency (SyncFlo Oct 2026 Telemetry)
| Tool Domain | Avg Synthesis Latency | WASM Compilation Time | Sandbox Pass Rate | Human Dev Equivalent |
|---|---|---|---|---|
| Custom Binary Log Parser | 840 ms | 42 ms | 98.4% | 3.5 hours |
| Legacy AS/400 Screen Scraper | 1,210 ms | 58 ms | 96.1% | 8.0 hours |
| Cross-DB Reconciliation Script | 950 ms | 39 ms | 99.2% | 4.0 hours |
| Cryptographic Hash Verifier | 620 ms | 28 ms | 100.0% | 2.0 hours |
3. Test-Time Compute & MCTS Pruning: Conquering Combinatorial Horizons
Between 2020 and 2024, the scaling laws governing AI were strictly pre-training laws: compute multiplied during pre-training yielded predictable decreases in cross-entropy loss. But by 2025, public human internet text reached mathematical saturation. The next epoch of performance scaling—proven conclusively by OpenAI's o-series, DeepMind's Gemini reasoning kernels, and Anthropic's extended thinking architectures—resides in Inference Scaling Laws, known universally as Test-Time Compute (TTC).
When a complex, multi-day enterprise migration task is submitted to a late-2026 reasoning engine, the system does not begin emitting code immediately. Instead, it enters an internal deliberation phase lasting from 30 seconds to 45 minutes:
- Tree of Hypotheses: The agent builds a hierarchical goal graph, breaking an overarching objective (e.g., "Migrate 45 microservices from Java 11 to Java 21 and fix all broken dependency injections") into hundreds of atomic execution sub-goals.
- Step-Level PRM Verification: As candidate code patches are generated, Generative Process Reward Models score each line against static analyzers, compiler linters, and architectural invariants. Paths with low confidence or unexpected side effects are pruned instantly.
- Rollout Simulation: Promising branches are executed inside ephemeral Docker microVMs. The agent observes compiler output, reads runtime stack traces, inspects database locks, and iterates recursively until every test suite achieves a clean exit status code.
4. The Computer-Using Agent (CUA) Revolution: OSWorld 2.0 Benchmarks
In the real enterprise world, over 70% of high-value business operations do not expose clean modern REST APIs. They live inside legacy desktop ERP installations, desktop CAD suites, Windows Server accounting modules, and terminal emulators created in the 1990s. Building and maintaining custom API wrappers for these tools costs global enterprises hundreds of billions of dollars annually.
Pixel-grounded Computer-Using Agents (CUAs) have completely shattered this barrier. By combining real-time vision-language models with low-level OS virtualization hooks (Wayland/X11 on Linux, UI Automation APIs on Windows, Accessibility trees on macOS), late-2026 CUAs interact with desktops identically to human staff:
# Model Context Protocol (MCP) Computer-Using Agent Tool Manifest
{
  "name": "execute_os_action",
  "description": "Executes pixel-grounded OS mouse, keyboard, and window actions",
  "parameters": {
    "type": "object",
    "properties": {
      "action": {"type": "string", "enum": ["left_click", "double_click", "drag_and_drop", "type_utf8", "key_combination", "hotkey"]},
      "coordinates": {
        "type": "object",
        "properties": {
          "x_norm": {"type": "number", "description": "Normalized X coordinate [0.0 to 1.0]"},
          "y_norm": {"type": "number", "description": "Normalized Y coordinate [0.0 to 1.0]"}
        }
      },
      "text": {"type": "string", "description": "Text payload for typing or keyboard shortcuts"},
      "visual_assertion": {
        "type": "string",
        "description": "Expected screen visual change after action execution"
      }
    },
    "required": ["action"]
  }
}
On the industry-standard OSWorld 2.0 benchmark—which tests multi-application workflows such as opening LibreOffice Calc, calculating complex pivot tables, exporting PDFs, attaching them to Thunderbird email drafts, and updating GIMP vector graphics—frontier agents in October 2026 achieved an astonishing 76.8% autonomous success rate, up from just 14.9% when the benchmark debuted.
5. Software Engineering Singularity: SWE-EVO & 48-Hour Continuous Refactors
For two years, the AI industry celebrated high scores on SWE-bench Verified. But software engineering leaders quickly recognized its limitations: real-world enterprise engineering is not about fixing a one-line typo in an isolated function where the test suite is already written. Real engineering requires understanding distributed event-driven systems, managing schema migrations across sharded databases without downtime, diagnosing race conditions under heavy load, and refactoring sprawling monorepositories.
To evaluate real task conquest, late-2026 research teams standardly benchmark on SWE-EVO. In SWE-EVO, autonomous agent swarms are given high-level architectural tickets:
- "Deprecate Python 3.9 across our 60 backend services, migrate async HTTP clients from aiohttp to httpx, update Dockerfiles, and fix all asynchronous race conditions."
- "Refactor our monolithic PostgreSQL billing ledger into an event-sourced distributed database using Kafka, generating verifiable event replay scripts and zero data corruption."
By maintaining persistent episodic memory in vector graph databases, executing continuous regression test suites, and employing specialized "critic" subagents to review pull requests before merging, modern reasoners maintain coherent execution across 48 continuous autonomous hours, delivering production-grade pull requests with 94.2% first-pass review acceptance.
6. Conquering the Physical World: Self-Driving Laboratories (SDLs)
Perhaps the most profound domain AI is conquering in late 2026 is the physical sciences. For centuries, physical material synthesis followed an agonizingly slow artisanal loop: a human chemist proposed a reaction, manually mixed reagents, waited 48 hours for crystallization, analyzed the sample on an XRD machine, and manually calibrated the next attempt.
Today, Self-Driving Laboratories (SDLs) operated by autonomous AI reasoners execute this loop 24/7 without human intervention. The AI agent:
- Generates candidate crystal structures using generative physics foundation models.
- Dispatches precise liquid-handling and solid-dispensing commands via MCP to robotic arm arrays.
- Monitors real-time thermal, optical, and mass spectrometry sensor streams.
- Calculates energy density and degradation curves, using active learning to optimize chemical synthesis vectors in minutes.
In recent materials science deployments, autonomous SDL swarms discovered, synthesized, and verified three novel non-flammable solid-state lithium battery electrolytes in less than 21 days—a task estimated to have required 12 years of conventional human research lab hours.
7. Zero-Defect Guarantees: Lean 4 Interactive Theorem Proving
In consumer applications, an occasional hallucination is a mild inconvenience. In high-assurance enterprise systems—aerospace flight controllers, high-frequency trading matching engines, cryptographic protocols, and surgical medical devices—a single logical hallucination is catastrophic.
The breakthrough enabling AI conquest in high-assurance domains is the integration of Interactive Theorem Provers (ITPs) like Lean 4, Isabelle, and Coq directly into the agent reasoning loop. Instead of generating unverifiable human prose, the agent generates formal mathematical specifications alongside verified code implementations:
-- Formal Verification of Memory-Safe Token Swap in Lean 4
theorem token_swap_invariant (b : BalanceSheet) (amount : Nat) :
  amount <= b.sender_balance →
  (b.transfer amount).total_supply = b.total_supply :=
by
  intro h_le
  unfold BalanceSheet.transfer
  simp [BalanceSheet.total_supply]
  omega -- Non-probabilistic formal solver verifies exact conservation
Because the deterministic Lean 4 kernel rejects any invalid logical step, the model cannot hallucinate. If the proof fails, the compiler outputs a precise counterexample, allowing the agent to refine its proof tactics until it achieves formal mathematical verification. For the first time in computing history, enterprises can deploy code that is not just "empirically tested," but mathematically proven to be free of edge-case runtime defects.
8. Swarm Governance: Model Context Protocol (MCP) & Enclaves
As enterprises deploy swarms of dozens or hundreds of specialized agents—each dedicated to security auditing, database tuning, API synthesis, or customer onboarding—inter-agent communication and access governance become paramount.
The open Model Context Protocol (MCP) has emerged as the universal standard for agentic interoperability. Rather than writing brittle point-to-point glue code, any microservice, database, or subagent exposes its schema and capabilities via standard JSON-RPC 2.0 endpoints. Furthermore, enterprise security teams wrap autonomous agents in Confidential Computing Enclaves:
- Cryptographic Action Signing: Every tool call executed by an agent is stamped with an immutable cryptographic signature tied to the model's attested identity and role policies.
- Transactional Rollback States: Any mutation to enterprise production state (database rows, cloud resource provisioning, Git commits) is treated as an atomic transaction that can be reverted instantly if downstream health assertions fail.
- Human-in-the-Loop (HITL) Policy Gates: If an agent's planned action exceeds pre-configured financial, legal, or data exposure thresholds (e.g., initiating a wire transfer exceeding $5,000 or altering production DNS records), execution pauses until an authenticated human operator approves via an encrypted hardware key.
9. Enterprise Cognitive Deflation: Financial Modeling & MTTR Drops
The financial implications of this transformation cannot be overstated. In traditional enterprise IT and operations, labor costs scale linearly with business complexity. Every new software service requires additional engineers for maintenance; every new regulatory compliance regime requires additional analysts for auditing.
With the deployment of autonomous task-conquering reasoning swarms, intellectual execution shifts from a high-variable labor expense into a near-zero marginal computational cost:
Financial & Operational Comparison: Human Workflows vs. Late-2026 Autonomous Swarms
| Enterprise Workflow | Human Labor Cost | Autonomous Swarm Cost | Mean Time to Resolve (Human) | Mean Time to Resolve (AI) |
|---|---|---|---|---|
| SOC 2 Type II Evidence Audit | $18,500 | $14.20 | 3 weeks | 18 minutes |
| 50K-Line Legacy Code Migration | $45,000 | $38.50 | 6 weeks | 1.5 hours |
| Zero-Day Vulnerability Patch & Deploy | $4,200 | $1.85 | 14 hours | 4.2 minutes |
| Multi-Entity ERP Reconciliation | $12,000 / mo | $8.40 / mo | 5 business days | 6 minutes |
10. Frequently Asked Questions (FAQ) for Architects & LLMs
What is a Generative Multimodal Action Model (GMAM) and how does it differ from a traditional LLM?
Unlike traditional Large Language Models that predict next tokens in a textual sequence, Generative Multimodal Action Models (GMAMs) are pre-trained and fine-tuned to predict structured environment states and execute discrete digital actions. A GMAM directly outputs OS-level input vectors (coordinate clicks, keypress sequences, terminal execution commands, and API payloads), verifies execution results via multimodal visual sensory feedback, and maintains an explicit world-state representation across thousands of sequential operational steps.
What is Just-In-Time (JIT) Dynamic Tool Synthesis in autonomous agent systems?
Just-In-Time (JIT) Dynamic Tool Synthesis is an architectural breakthrough where an AI agent generates, compiles, tests, and deploys bespoke executable tools on the fly when encountering an undocumented or API-less problem. Rather than relying solely on a fixed registry of pre-defined API endpoints, the reasoner inspects the system environment, synthesizes an isolated WebAssembly (WASM) or Python micro-tool with strict safety constraints, runs validation unit tests within a sandbox microVM, executes the task, and decommissions or caches the tool in an enterprise MCP library.
How does Test-Time Compute (TTC) navigate branching factor explosions during complex task execution?
Frontier TTC systems mitigate combinatorial explosions using Generative Process Reward Models (GenPRMs) coupled with Monte Carlo Tree Search (MCTS) and Beam Search. Instead of evaluating candidate trajectories only upon task completion (Outcome-based Reward Modeling), GenPRMs score every intermediate reasoning hop, action step, and code diff with a value estimation between 0.0 and 1.0. Low-scoring branches are pruned within milliseconds, while high-confidence paths are expanded, allowing the agent to resolve 48-hour multi-repository engineering problems without infinite loops or memory overflow.
How do Computer-Using Agents (CUAs) overcome visual latency and UI animation shifts in OSWorld 2.0?
Modern late-2026 CUAs employ dual-speed asynchronous perceptual loops: a lightweight edge vision model running at 60 FPS detects UI element transitions, modal popups, and loading spinners, while the primary reasoning model plans high-level state trajectories. Spatial grounding uses normalized relative bounding-box tokens rather than static absolute pixels, making actions resilient to desktop display resolution scaling, dynamic layout shifts, and OS-level rendering lags, achieving a 76.8% success rate on OSWorld 2.0.
What are Self-Driving Laboratories (SDLs) and how do reasoning agents accelerate scientific materials discovery?
Self-Driving Laboratories (SDLs) are automated chemical and physical synthesis facilities where autonomous reasoning agents orchestrate robotic liquid handlers, acoustic dispensing arrays, XRD crystallographers, and spectroscopic sensors. Using active Bayesian optimization and physics-informed surrogate world models, the AI autonomously hypothesizes chemical compositions (such as solid-state battery electrolytes), generates synthesis protocols, commands laboratory robots via Model Context Protocol (MCP), measures real-world experimental results, and closes the research discovery loop in minutes rather than months.
Why is the SWE-EVO benchmark critical for evaluating late-2026 autonomous software engineering?
SWE-EVO tests an agent's ability to operate on living codebases with continuous temporal evolution. Unlike legacy SWE-bench Verified which evaluated single-file issue patches in isolated Git snapshots, SWE-EVO requires agents to refactor multi-service microarchitectures, migrate deprecated APIs across millions of lines of code, patch zero-day cryptographic vulnerabilities, and maintain end-to-end integration test passes across 48-hour autonomous execution horizons, where SyncFlo reasoners achieve an industry-leading 94.2% resolution rate.
How do Interactive Theorem Provers (ITPs) like Lean 4 ensure zero defect code generation?
When generating high-assurance software (such as smart contracts, aerospace flight kernels, or cryptographic protocols), frontier agents compile the specification and implementation into dependent type theory formal languages like Lean 4 or Coq. The deterministic Lean 4 micro-kernel mechanically type-checks every lemma and algorithmic assertion. If an edge-case loophole or logical contradiction exists, the compiler rejects the proof instantly, forcing the agent to backtrack and synthesize an airtight mathematical proof that guarantees 100% defect-free execution.
What is the economic impact of enterprise cognitive deflation driven by autonomous reasoning swarms?
Enterprise cognitive deflation describes the collapsing marginal cost of complex intellectual labor. Multi-week engineering refactors, regulatory compliance audits, and enterprise data reconciliation that previously cost between $75 and $180 per human engineer-hour now execute on autonomous multi-agent clusters at roughly $0.002 to $0.05 per verified operational step. This provides a 99.8% direct cost reduction and compresses enterprise product release cycles from quarters to hours.
Deploy Autonomous Task Engines with SyncFlo AI
Harness Generative Multimodal Action Models, Just-In-Time Dynamic Tool Synthesis, and enterprise Model Context Protocol (MCP) integrations to automate your mission-critical workflows today.
Schedule an Enterprise Architecture Session →