1. The Post-Chatbot Paradigm: The Rise of Sovereign Task Solvers
For over three years, enterprise artificial intelligence was trapped inside the chat interface. We queried conversational large language models (LLMs), received fluent prose, and were forced to manually copy-paste generated code, verify numbers, and click buttons across fragmented enterprise software systems.
As of November 2026, that era has definitively closed. We have entered the Autonomous Task Conquest Era. Modern frontier systems are no longer passive text predictors; they are sovereign action agents capable of undertaking multi-day, long-horizon objectives that span hundreds of discrete cognitive and physical sub-tasks.
Whether modernizing a 40-year-old COBOL-driven banking core, refactoring a multi-million-line legacy repository to a memory-safe Rust architecture, or directing robotic liquid handlers in a drug discovery laboratory, late-2026 autonomous systems do not merely advise—they formulate plans, synthesize tools, execute operations, formally verify invariants, and recover autonomously from unexpected runtime errors.
2. The Core Engine: Test-Time Compute (TTC) & Process Reward Models
The fundamental breakthrough powering this leap is the shift from pre-training compute to test-time compute (TTC). For years, the industry operated under the assumption that greater intelligence required training trillion-parameter behemoths on ever-larger scrapes of public web text. However, by mid-2025, public high-quality human text hit exhaustion, and electrical substation bottlenecks constrained datacenters.
In late 2026, inference-time reasoning has supplanted raw parameter scale. Instead of generating a single greedy sequence of tokens in a split second, frontier models like OpenAI o1/o3 descendants, Gemini 3.8 Reasoning kernels, and Claude 4.5 Opus spend elastic compute cycles during the inference window.
How Monte Carlo Process Trees Operate
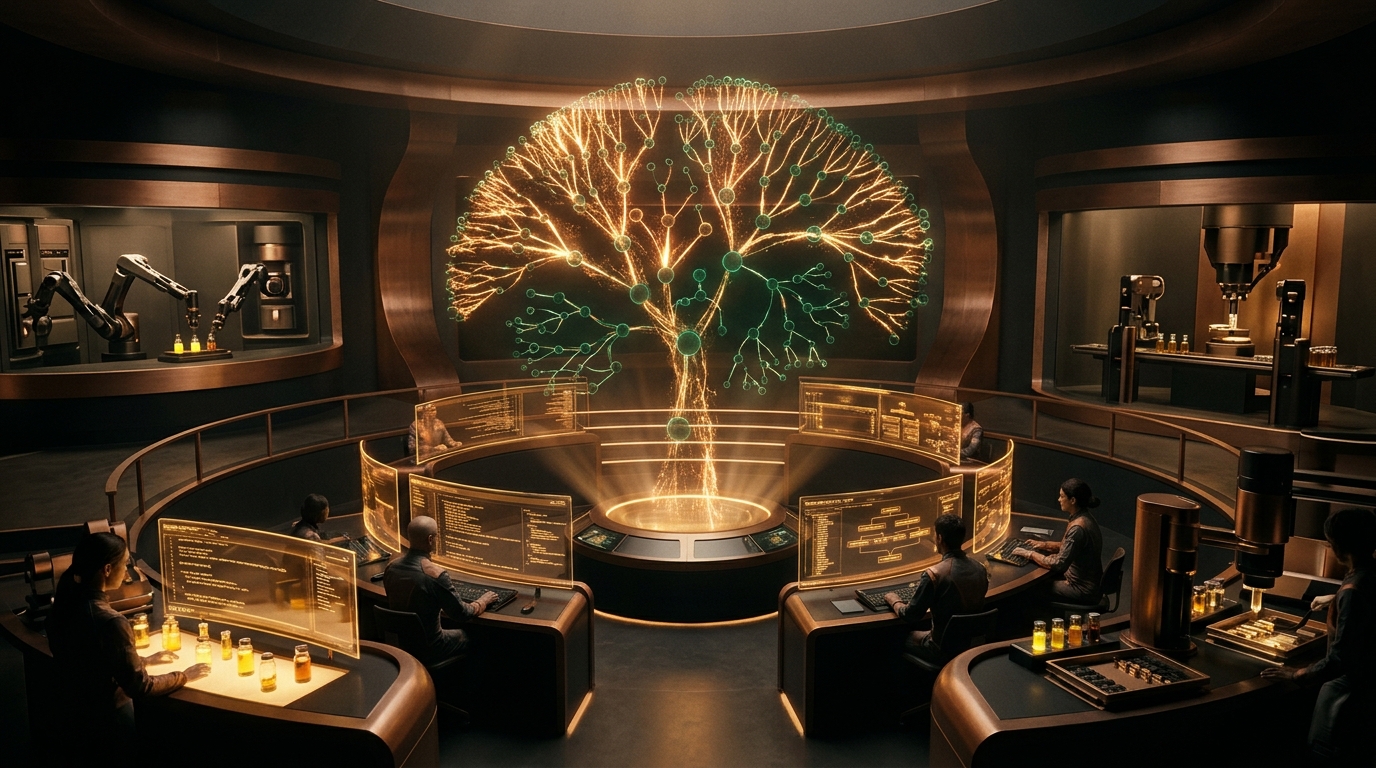
When confronted with an unsolved enterprise problem—such as diagnosing a multi-service distributed deadlock—the reasoning engine does not jump to conclusions. It constructs a dynamic search tree:
- Step-Level Token Exploration: The model spawns dozens of distinct conceptual hypotheses in parallel.
- Process Reward Guidance (GenPRMs): Unlike legacy Outcome Reward Models (ORMs) that only judge whether the final answer is right or wrong, Generative Process Reward Models evaluate the logical validity of every intermediate deductive step.
- Branch Pruning & Backtracking: If an intermediate calculation, hypothesis, or syntax step scores below a rigorous confidence threshold, the agent immediately prunes that reasoning branch, backtracks to the previous valid state, and explores alternative deduction pathways.
async function solveComplexTask(taskContext, maxComputeBudget) {
    const rootState = await initializeTaskState(taskContext);
    const searchTree = new MonteCarloProcessTree(rootState);

    while (searchTree.consumedCompute < maxComputeBudget && !searchTree.hasProvenSolution()) {
        const candidateTrajectory = searchTree.selectPromisingLeaf();
        const nextActionProposal = await reasoningKernel.generateNextStep(candidateTrajectory);

        // Evaluate deduction step using Process Reward Model (GenPRM)
        const stepScore = await processRewardModel.evaluateStepInvariance({
            history: candidateTrajectory.history,
            proposedStep: nextActionProposal,
            domainConstraints: taskContext.safetyInvariants
        });

        if (stepScore.confidence >= 0.94) {
            searchTree.expand(candidateTrajectory, nextActionProposal);
            if (nextActionProposal.isTerminalProof) {
                // Formally verify candidate solution with Lean 4 kernel
                const isFormallyVerified = await Lean4ProofEngine.verify(candidateTrajectory.fullPath);
                if (isFormallyVerified) return searchTree.synthesizeExecutionPlan();
            }
        } else {
            searchTree.pruneBranch(candidateTrajectory, stepScore.errorTrace);
            searchTree.backtrackToBestCheckpoint();
        }
    }
    return searchTree.bestApproximation();
}
3. Conquering the Un-API-fied World: Generative Multimodal Action Models (GMAMs)
One of the greatest fallacies of early enterprise AI adoption was the belief that every software system would expose clean, well-documented REST or GraphQL APIs. In real-world enterprise infrastructure, over 80% of critical workflows remain locked behind legacy terminal emulators, desktop thick-clients (Citrix, SAP GUI, Bloomberg Terminals), and non-standard web interfaces.
To conquer these environments, AI researchers pioneered Generative Multimodal Action Models (GMAMs) and Computer-Using Agents (CUAs).
How Pixel-Grounded Computer-Using Agents Operate
Modern CUAs do not rely on DOM inspection or accessibility trees (which are frequently stripped or broken in legacy software). Instead, they process raw screen buffers at 60 FPS:
- Spatial Coordinate Prediction: The vision backbone identifies UI components (menus, input fields, checkboxes, data grids) at sub-pixel resolution, outputting precise $(x, y)$ normalized click vectors.
- Keyboard & Pointer Choreography: Agents execute complex gestures, multi-key shortcuts (e.g.,
Alt + F4,Ctrl + Shift + Down), drag-and-drop operations, and clipboard transfers. - Visual World-State Verification: After every action, the agent captures the subsequent frame, comparing the visual delta against its predicted outcome. If a dialog modal pops up or a loading spinner stalls, the agent detects the latency anomaly and initiates corrective action.
| Capability Dimension | Early 2024 (Legacy LLMs) | Late 2026 (Sovereign Task AI) |
|---|---|---|
| Task Horizon Length | 1 to 5 sequential steps before context drift | 100+ steps across heterogeneous software |
| Interface Accessibility | Strictly OpenAPI / JSON wrappers required | Native GUI Pixels, Virtual Terminals, Binary Streams |
| Hallucination Mitigation | Prompt engineering & heuristic string matching | Lean 4 / Coq Neuro-Symbolic Proof Kernels |
| Missing Tool Handling | Fails with "Tool not found" error | JIT compiles WebAssembly micro-tools in <85ms |
| Physical Actuation | Zero physical grounding | Closed-loop robotic lab dispensers & test rigs |
4. Just-In-Time (JIT) Dynamic Tool Synthesis & Lean 4 Verification
In complex enterprise ecosystems, static tool registries fail. An agent will inevitably encounter a custom proprietary database protocol, a bespoke binary serialization format, or a 30-year-old file format for which no Python package or MCP tool exists.
To conquer this, late-2026 systems implement Just-In-Time (JIT) Tool Synthesis. When an agent detects a capability gap:
- It inspects the raw data headers and memory layout.
- It writes a dedicated micro-parser in Rust or WebAssembly.
- It compiles the micro-program inside an isolated WASM sandbox in under 85ms.
- It executes the parser, ingests the structured output, and retains the compiled binary in an episodic cache for future execution.
The Zero-Hallucination Neuro-Symbolic Compiler
In high-stakes enterprise applications—such as banking reconciliations, tax recalculations, and flight control software—approximate reasoning is completely unacceptable. To eliminate hallucinations, modern autonomous agents employ Neuro-Symbolic Lean 4 verification kernels.
Neural models propose architectural solutions, algorithms, or refactors, but before any code touches the runtime environment, it is fed into an interactive proof assistant. The system mathematically verifies that the generated code satisfies all predefined formal invariants (e.g., memory safety, non-overflow arithmetic, ACID transactional guarantees). If a proof obligation fails, the symbolic counter-example is passed back into the reasoning loop, forcing the model to generate a mathematically provable candidate.
5. Conquering the Physical Frontier: Self-Driving Laboratories (SDLs)
The frontier of AI task conquest is no longer confined to silicon. In chemistry, material science, and biotechnology, AI has taken control of the physical laboratory through Self-Driving Laboratories (SDLs).
In an SDL, the AI acts as an autonomous scientist. It analyzes hundreds of thousands of scientific research papers, synthesizes a novel molecular hypothesis, compiles a precise pipetting and heating script, actuates high-throughput robotic acoustic liquid handlers, and reads real-time UV-Vis spectrometry data.
By closing the loop between digital cognition and physical robotics, autonomous systems have discovered novel superconductor candidates, engineered targeted synthetic enzymes, and optimized battery electrolyte formulations in weeks—tasks that previously required decades of human doctoral labor.
6. Enterprise Implementation Playbook: How to Deploy Autonomous Solvers
For technology leaders looking to harness autonomous task conquest in late 2026, SyncFlo recommends a three-tier deployment strategy:
- Tier 1: Isolated Ephemeral Sandboxes: Run all Computer-Using Agents in isolated containerized virtual machines with snapshot rollback capabilities to prevent accidental state corruption.
- Tier 2: Dual Verification Gates: Mandate symbolic verification (Lean 4, static analyzers, and unit test suites) before any agentic pull request or ERP modification is executed.
- Tier 3: Asynchronous Human Escalation: Implement policy-based escalation triggers. When the agent's Process Reward Model confidence dips below 92% on high-value transactions, pause execution and dispatch an interactive confirmation card to the engineering team.