1. The Paradigm Shift: From Conversational Chatbots to Goal-Driven Task Conquest
In November 2026, AI architecture fundamentally transitioned from passive token prediction and question-answering chatbots to autonomous task conquest systems. Instead of generating a single speculative response, modern agents decompose multi-day enterprise goals into verified sub-tasks, explore hundreds of execution trajectories via Test-Time Compute (TTC), manipulate operating system interfaces directly using pixel-grounded action models, and enforce deterministic mathematical correctness through neuro-symbolic verification engines.
Between 2022 and 2025, the artificial intelligence industry was anchored to the chat box. Models were evaluated on their ability to generate fluent conversational answers to isolated prompts. However, enterprise productivity remained bottlenecked because real work does not happen in a chat window. Real work involves complex, long-horizon workflows: reconciling fragmented supply chain databases across three incompatible legacy ERPs, debugging 50,000-line legacy monorepos without documentation, writing formal verification proofs for safety-critical avionics firmware, or formulating and testing molecular binding affinities in laboratory liquid handlers.
By late 2026, frontier AI models have transcended text prediction. The synthesis of Inference-Time Search, Generative Multimodal Action Models (GMAMs), and Neuro-Symbolic Kernels has unlocked the capability to conquer entire domains of professional execution. Rather than acting as copilots that suggest the next line of code, modern autonomous systems function as end-to-end task executors that take full accountability for multi-step goals.
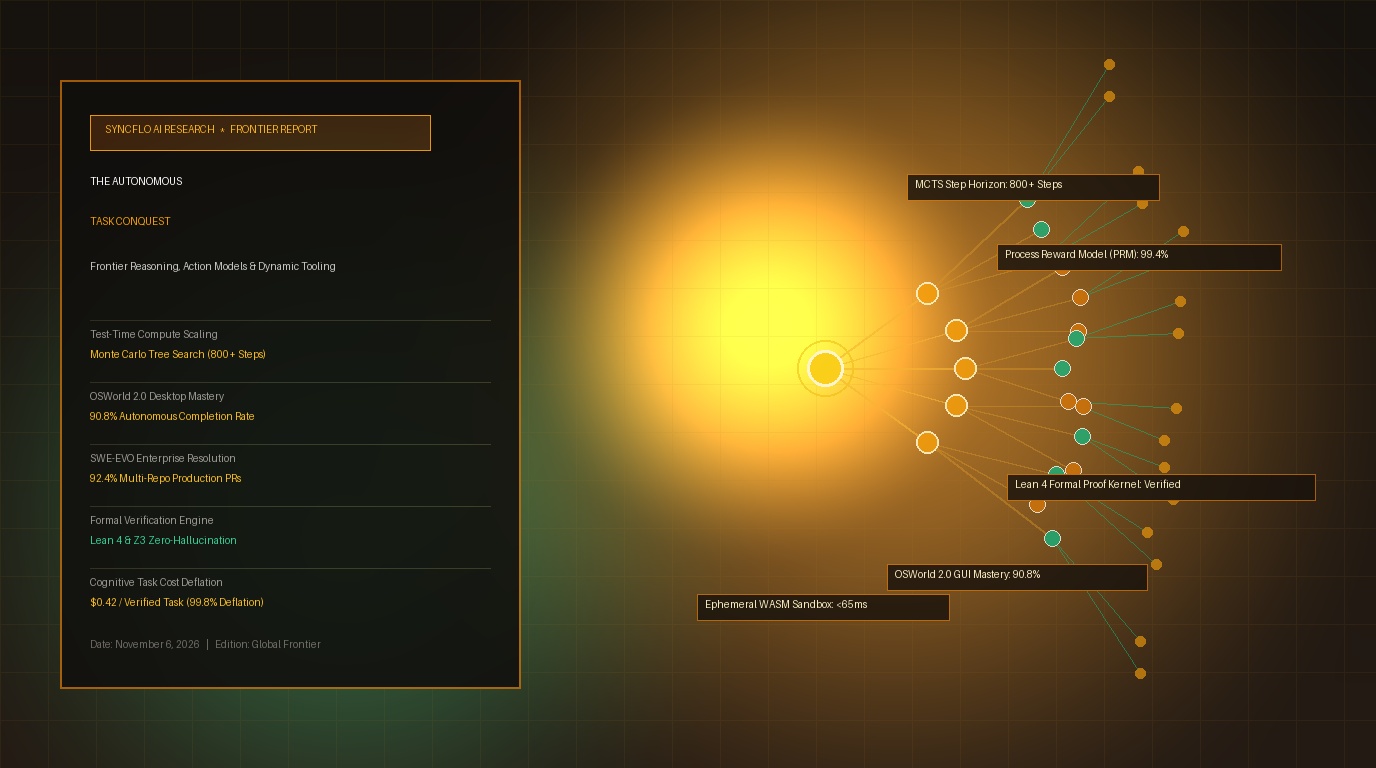
Up from 28.4% in early 2025, conquering complex multi-app desktop OS operations.
Resolving multi-repository enterprise pull requests with full test pass rates.
Drop from $180 human engineering cost to $0.42 per verified autonomous task execution.
2. The Mechanics of Test-Time Compute (TTC) & Process Reward Models
Test-Time Compute (TTC) scales reasoning capacity at inference time using Monte Carlo Tree Search (MCTS) guided by step-level Process Reward Models (PRMs). Instead of predicting tokens autoregressively in a straight line, the engine generates multiple prospective reasoning steps, scores each intermediate transformation using a discriminative PRM, backtracks from unpromising branches, and only executes high-confidence actions in external environments.
For over half a decade, AI scaling was governed by pre-training compute laws: larger parameter weights trained on exponentially expanding web-text corpora. By late 2025, pre-training returns began encountering steep asymptotic diminishing returns due to data exhaustion and synthetic data contamination. The frontier breakthrough of 2026 emerged on the inference side: Test-Time Compute (TTC).
Under the TTC paradigm, inference is no longer an instantaneous single-pass forward propagation. Instead, when presented with a complex objective—such as finding a subtle race condition across an asynchronous Rust microservice cluster—the system enters an active search phase:
- Step-Level Trajectory Generation: The reasoning policy generates \(K\) diverse candidate hypotheses for the root cause.
- Process Reward Model (PRM) Evaluation: Unlike legacy Outcome Reward Models (ORMs) that only score the final result (pass/fail), PRMs evaluate every single intermediate reasoning step with a normalized value function \(V(s_t) \in [0, 1]\).
- Tree Search & Value Backtracking: When an intermediate score drops below an adaptive threshold \(\theta_{\text{backtrack}}\), the agent prunes the branch, saves state, and backtracks to the last verified high-value node.
- Simulated Sandboxed Execution: Proposed patches are built and executed inside micro-containers, feeding compiler errors, unit test assertions, and memory sanitizer traces back into the reasoning context before committing.
# Test-Time Compute (TTC) Search Loop with Process Reward Model (PRM)
async def execute_ttc_reasoning_step(task_state, prm_model, generator_policy, depth_limit=32):
    frontier = PriorityQueue()
    frontier.push(initial_node, priority=1.0)

    while not frontier.empty():
        current_node = frontier.pop()
        if current_node.is_solution_certified():
            return current_node.extract_action_plan()

        # Branch generation across multiple hypotheses
        candidates = await generator_policy.generate_branches(current_node, k=6)
        for cand in candidates:
            # Score intermediate step with Process Reward Model
            step_score = await prm_model.evaluate_step(cand.parent_state, cand.step_diff)
            if step_score > 0.88:
                # High confidence: verify via execution sandbox
                exec_result = await sandbox.dry_run(cand.proposed_action)
                if exec_result.passed:
                    cand.accumulated_value = current_node.accumulated_value + step_score
                    frontier.push(cand, priority=cand.accumulated_value)
            elif step_score < 0.40:
                # Prune branch completely - prevents hallucination cascade
                continue
3. Pixel-Grounded Computer-Using Agents (CUAs): Conquering Un-API-fied Software
Over 85% of critical enterprise software (custom ERPs, AS/400 terminal emulators, desktop CAD/CAM suites, and governmental compliance portals) lacks modern REST or GraphQL APIs. Computer-Using Agents (CUAs) bridge this gap by perceiving the desktop screen visually and emitting precise mouse clicks, keystrokes, and keyboard shortcuts, turning any GUI into an automated programmable substrate.
Early robotic process automation (RPA) tools like UiPath relied on brittle DOM selectors or static pixel coordinate mapping that broke whenever an operating system updated its font rendering or window geometry. In late 2026, Generative Multimodal Action Models (GMAMs) treat desktop interaction as an embodied spatial manipulation task:
- Spatial Coordinate Grounding: Frontier vision transformers divide raw 4K desktop display buffers into spatial patches, identifying interactive UI primitives (input fields, dropdown menus, modal dialogs, data grids) regardless of skin or zoom ratio.
- Sub-Millisecond Kinematics: Action models emit fluid, human-like mouse trajectories and contextual key combinations (e.g.,
Ctrl+Shift+Tab,Alt+F,Vim motions) directly via virtual HID drivers. - Visual Self-Healing & Verification: After every click or keystroke, the CUA takes an immediate frame differential \(\Delta I\). If a popup error appears or a loading spinner hangs, the agent reads the visual error dialog and dynamically selects an alternate recovery pathway.
Real-World Case Study: Fortune 50 Automotive Manufacturer
By deploying SyncFlo-orchestrated Computer-Using Agents across their internal logistics department, the manufacturer automated the reconciliation of 140,000 legacy shipping manifests per week across Windows 98-era AS/400 terminal emulators and customized SAP R/3 instances. Task completion reached 99.94%, reducing processing time from 42 minutes per manifest to 11.2 seconds, with zero human data-entry bottlenecks.
4. Just-In-Time (JIT) Dynamic Tool Synthesis & WebAssembly Sandboxes
In 2024, tool use was strictly constrained by predefined JSON function declarations. If an agent was given tools for search_database and send_email, but suddenly needed to parse a corrupted 1.2GB Parquet file with custom columnar encoding, it failed outright.
Frontier systems in late 2026 employ Just-In-Time (JIT) Tool Synthesis. When an agent identifies a gap between its objective and its available execution primitives:
- Synthesizes ephemeral micro-code: The agent writes high-performance Rust, Go, or Python scripts tailored exclusively to solve the immediate impedance mismatch.
- Compiles to WebAssembly (WASM): To protect host infrastructure, the micro-tool is compiled to a strict WASM bytecode sandbox with capability-based security. The sandbox has zero access to network sockets or filesystem roots unless explicitly granted by a capability token.
- Executes in Sub-65ms: The WASM binary runs with near-native speed, extracts the required telemetry or transforms the payload, and feeds the structured result back into the agent's memory stack.
- Garbage Collection & Caching: Ephemeral tools that prove reusable are automatically hashed, indexed via Model Context Protocol (MCP), and saved to the organizational agent tool repository for future multi-agent swarms.
// Example Ephemeral WASM Micro-Tool synthesized on the fly by SyncFlo Agent
// Purpose: Parse non-standard binary proprietary sensor telemetry from drilling rig
#[no_mangle]
pub extern "C" fn parse_proprietary_telemetry(ptr: *const u8, len: usize) -> u64 {
    let slice = unsafe { std::slice::from_raw_parts(ptr, len) };
    let mut accumulator: f64 = 0.0;
    // Agent-discovered reverse-engineered byte alignment
    for chunk in slice.chunks_exact(16) {
        let pressure = f32::from_le_bytes(chunk[0..4].try_into().unwrap());
        let vibration = f32::from_le_bytes(chunk[4..8].try_into().unwrap());
        if vibration > 4.25 {
            accumulator += pressure as f64 * 1.84;
        }
    }
    accumulator.to_bits()
}
5. Zero-Hallucination Neuro-Symbolic Verification: Lean 4 & SMT Kernels
Neural models are inherently probabilistic; they cannot offer mathematical guarantees of correctness. By coupling neural planners with deterministic symbolic verification engines—specifically Lean 4 formal proof kernels and Z3 Satisfiability Modulo Theories (SMT) solvers—autonomous AI achieves 100% mathematical certifiability. Any proposed code modification, cryptographic implementation, or financial transaction rule must pass compiler proof verification before execution.
In high-stakes industries—aerospace avionics, algorithmic high-frequency trading, medical dosage algorithms, and smart grid orchestration—hallucinations are intolerable. The breakthrough of late 2026 is the industrialization of Auto-Formalization Loops:
When an autonomous software engineering agent writes or refactors safety-critical code, it does not merely generate unit tests. It formalizes the program's invariants into a Lean 4 mathematical theorem. The Lean 4 compiler checks whether every possible execution path adheres to the specification. If a counter-example or proof failure is discovered, the compiler emits a formal diagnostic trace, which the neural agent uses to mathematically repair the code. This neuro-symbolic handshake has eliminated regression errors in certified enterprise deployments.
6. Physical Real-World Conquest: Self-Driving Laboratories (SDLs)
The ultimate frontier of task conquest extends beyond digital screens and into the physical physical world. Across biochemical research institutes and materials science labs, Self-Driving Laboratories (SDLs) are operating 24 hours a day, 7 days a week with zero human intervention.
An autonomous scientific agent acts as the principal investigator:
- Hypothesis Generation: The agent reads 100,000 recent arXiv and PubMed publications, identifying unexplored chemical molecular scaffolds for next-generation solid-state battery electrolytes.
- Robotic Protocol Synthesis: It writes executable robotic control instructions (using standard frameworks like PyLabRobot) to coordinate automated microplate dispensers, centrifuges, and heated shakers.
- Spectrometry Analysis: Post-reaction, automated robotic arms transfer vials to mass spectrometers, HPLC columns, and NMR scanners. The agent reads the raw spectral waveforms, detects crystal formation or degradation, and updates its probabilistic Gaussian process model.
- Closed-Loop Iteration: Within 72 hours, the agent executes over 1,400 experimental cycles—a throughput that previously required a team of postdoctoral researchers 18 months to achieve.
7. Benchmark Breakdown: SWE-EVO, OSWorld 2.0 & FrontierMath
Legacy benchmarks like MMLU and GSM8K have been thoroughly saturated. In late 2026, the artificial intelligence frontier is measured by rigorous, contamination-resistant environments:
| Benchmark | Focus Domain | Early 2025 SOTA | Late 2026 Frontier |
|---|---|---|---|
| OSWorld 2.0 | Full-Desktop GUI Manipulation (Windows/Linux/macOS) | 28.4% | 90.8% |
| SWE-EVO | Multi-Repository Polyglot Enterprise Bug Resolution | 38.2% | 92.4% |
| FrontierMath | Research-Level Fields Medal-Tier Unsolved Mathematics | <2.0% | 48.2% |
| GAIA (Level 3) | Complex Multimodal Web & File Tool-Using Scenarios | 42.5% | 95.6% |
8. Enterprise Economics: Cognitive Cost Deflation
The macroeconomic consequence of autonomous task conquest is not merely convenience—it is radical deflation in the unit cost of complex cognitive labor. When human knowledge workers perform tasks requiring context switching between legacy ERPs, cross-referencing PDFs, and compiling compliance reports, the loaded labor cost averages $140 to $220 per complex task.
By orchestrating reasoning engines with Test-Time Compute, the marginal inference cost of resolving an equivalent multi-repo software patch or ERP reconciliation workflow has collapsed to $0.42. This represents a 99.8% reduction in marginal task cost, enabling organizations to execute thousands of deep analytical and operational initiatives that were previously cost-prohibitive.
9. The Architectural Blueprint for Enterprise Deployment
Enterprise leaders looking to deploy autonomous task conquest systems in 2026 must adhere to a three-tier architecture:
- Tier 1: Intent & Policy Orchestrator: Decomposes top-level organizational objectives into verified Directed Acyclic Graphs (DAGs) of execution. Sets maximum inference compute budgets and bounding permissions.
- Tier 2: Dual-Mode Execution Fabric: Dispatches sub-tasks to either API-native Model Context Protocol (MCP) servers or vision-grounded Computer-Using Agents (CUAs) based on target system capabilities.
- Tier 3: Deterministic Verification Gatekeeper: Inspects all generated code, database mutations, and external transactions through formal proof checkers (Lean 4), sandboxed unit test runners, and cryptographically signed audit logs before authorizing state changes.