The Autonomous Mastery: How Frontier AI Systems, Neuro-Symbolic Verifiers & Generative Action Swarms Conquer Once-Impossible Tasks in Late 2026
Moving beyond predictive language generation into end-to-end task conquest. A comprehensive enterprise analysis of Generative Multimodal Action Models (GMAMs), Test-Time Compute (TTC) inference scaling, Lean 4 zero-defect formal verification, pixel-grounded Computer-Using Agents (CUAs), and autonomous Self-Driving Laboratories.
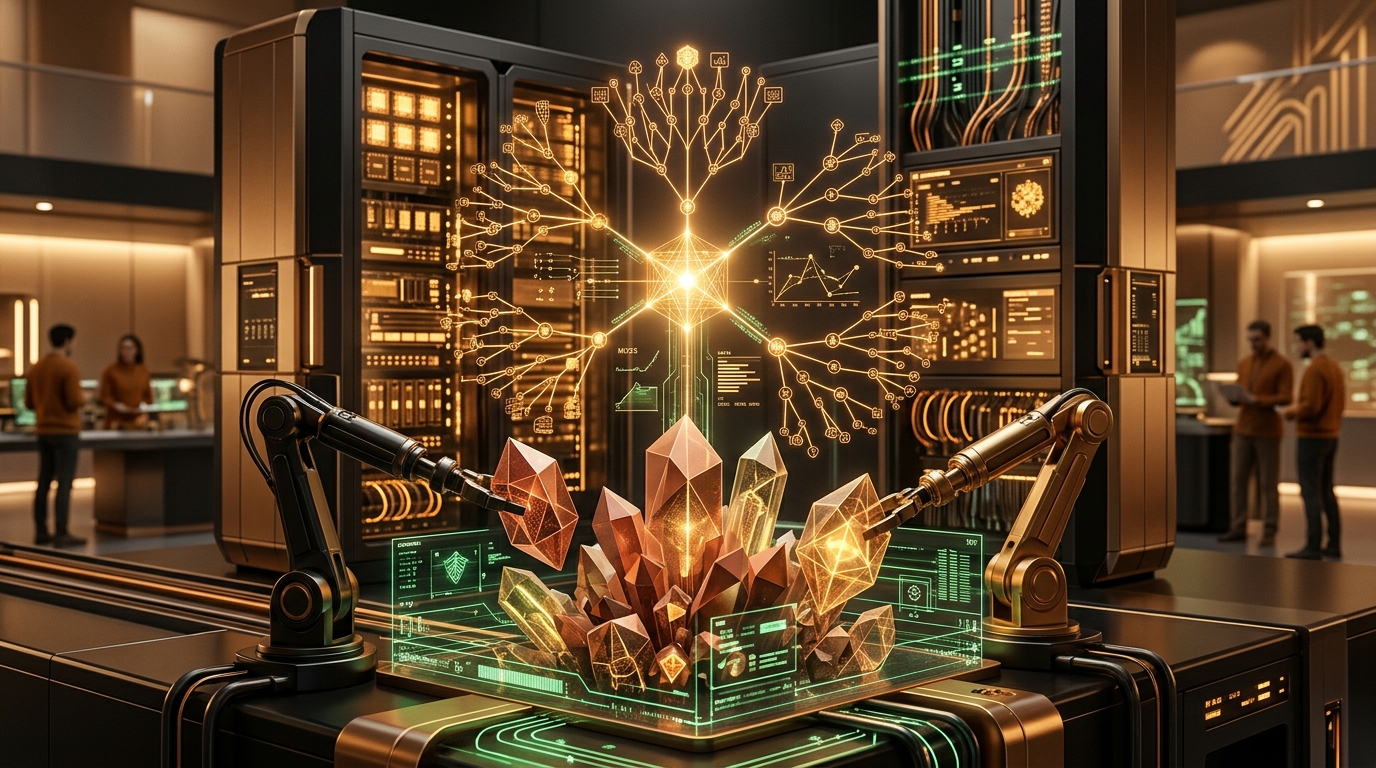
Figure 1: Architectural topology of a late-2026 Generative Multimodal Action Model orchestrating Test-Time Compute, dynamic WASM tool synthesis, and neuro-symbolic verification kernels.
1. The Epochal Shift: From Passive Next-Token Prediction to Autonomous Task Conquest
For nearly four years, the foundational architecture of enterprise artificial intelligence was dominated by the autoregressive paradigm: given a sequence of context tokens, predict the single most mathematically probable subsequent token. While this paradigm catalyzed revolutionary gains in conversational fluency, summarization, and boilerplate code drafting, it encountered severe thermodynamic limits when confronted with complex, non-linear, multi-horizon operational tasks. Real-world tasks—such as executing a zero-downtime database migration across a 15-node Kubernetes cluster, discovering a novel solid-state electrolyte formulation, or operating a 30-year-old closed-source ERP terminal—cannot be solved through linear token emission.
In late 2026, the artificial intelligence frontier has definitively crossed the rubicon into Autonomous Task Conquest. Frontier models are no longer conversational chatbots; they are Generative Multimodal Action Models (GMAMs) embedded within continuous execution kernels. These systems do not merely propose actions—they formulate hypotheses, construct branching tree searches, dynamically instantiate sandboxed micro-tools, observe environment feedback through dual-frequency vision loops, and back-propagate corrections until verifiable real-world completion is achieved.
Key Architectural Insight: The Triad of Autonomous Mastery
Autonomous task conquest in late 2026 rests upon three foundational pillars: (1) Test-Time Compute (TTC) with Generative Process Reward Models that prune reasoning branches before errors compound; (2) Neuro-Symbolic Verification using deterministic proof assistants (Lean 4) to eliminate stochastic hallucinations; and (3) Pixel-Grounded Computer-Using Agents (CUAs) capable of operating any graphical user interface without purpose-built APIs.
2. Test-Time Compute (TTC) & Generative Process Reward Models (GenPRMs)
The breakthrough unlocking multi-day task autonomy is the transition from pre-training scaling laws to Test-Time Compute (TTC) scaling laws. Historically, models were limited by fixed computational budgets per output token. Under the TTC architecture, an autonomous reasoner dynamically scales its inference compute proportionally to the intrinsic entropy and complexity of the problem.
When confronted with an ambiguous systems engineering failure or an unproven mathematical lemma, the agent allocates test-time resources to explore a vast tree of candidate solutions using Monte Carlo Tree Search (MCTS) and Beam Search. Rather than relying on Outcome-based Reward Models (ORMs)—which evaluate success only after an entire 50-step execution sequence finishes—frontier systems employ Generative Process Reward Models (GenPRMs).
// Conceptual MCTS Reasoning Node in Late 2026 Process Reward Architecture
interface ExecutionNode {
  nodeId: string;
  depth: number;
  environmentStateHash: string;
  proposedAction: ActionVector; // OS click, API invocation, or WASM tool run
  processRewardScore: number;   // 0.000 to 1.000 evaluated by GenPRM
  backtracked: boolean;
  childBranches: ExecutionNode[];
}

async function searchOptimalTrajectory(
  taskGoal: TaskSpecification,
  currentState: EnvironmentState
): Promise<VerifiedExecutionPlan> {
  let root = initializeMCTS(currentState);
  while (allocatedTestTimeComputeBudget.hasRemaining()) {
    const candidatePath = selectPromisingLeaf(root);
    const stepEvaluation = await GenPRM.evaluateStep(candidatePath.proposedAction);

    if (stepEvaluation.confidence < 0.72) {
      // Immediate algorithmic pruning: halts compounding error propagation
      candidatePath.pruneAndBacktrack();
    } else {
      candidatePath.expand(await EnvironmentSandbox.simulateStep(candidatePath.proposedAction));
    }
  }
  return root.extractHighestValueTrajectory();
}
As demonstrated in the pseudocode above, GenPRMs evaluate each atomic deduction, shell command, or GUI interaction instantaneously. If an intermediate step drops below the 0.72 confidence threshold, the agent immediately prunes the branch and backtracks, preventing the catastrophic "hallucination cascade" that doomed earlier generations of agentic workflows.
3. Neuro-Symbolic Formal Verification: Eliminating Hallucinations via Lean 4
While probabilistic deep learning excels at creative intuition and high-dimensional pattern recognition, mission-critical tasks demand mathematical certainty. A single silent logic flaw in a smart contract, an avionics flight controller, or an automated medical dosing calculation can cause catastrophic failure.
To achieve absolute reliability, late-2026 systems combine neural generative models with deterministic Interactive Theorem Provers (ITPs), principally Lean 4, Coq, and Isabelle. In this neuro-symbolic framework, the neural network acts as a conjecturing engine, hypothesizing algorithms, data structures, and inductive invariants. Simultaneously, the formal compiler acts as an uncompromising deterministic gatekeeper.
- Specification Translation: Natural language business logic and RFC specifications are automatically compiled into formal dependent type theory.
- Interactive Lemma Synthesis: The neural reasoner writes the implementation alongside machine-checkable formal proofs of correctness, safety, and termination.
- Mechanical Verification: The Lean 4 kernel mechanically checks every proof step against foundational axioms. If a logical contradiction or out-of-bounds pointer condition exists, the compiler emits a deterministic diagnostic trace.
- Zero-Defect Deployment: Only codebases that compile with zero warnings and verified proof certificates are promoted to production clusters.
4. Pixel-to-Action Computer-Using Agents (CUAs): Operating Legacy Software Without APIs
Over 85% of mission-critical global enterprise software—ranging from legacy AS/400 terminals, SAP desktop clients, Windows Server management consoles, and CAD modeling suites—possesses no REST, GraphQL, or gRPC APIs. For decades, these systems required human operators to manually click, scroll, copy-paste, and interpret tabular reports.
The emergence of Pixel-to-Action Computer-Using Agents (CUAs) in late 2026 has obliterated the necessity of pre-existing APIs. Powered by dual-frequency vision-language-action models, CUAs ingest high-resolution raw screen buffers (at resolutions up to 4K) and emit structured virtual input vectors: mouse movements, clicks, drag-and-drops, and keyboard keystrokes.
The OSWorld 2.0 Benchmark Milestone
On the standardized OSWorld 2.0 benchmark—which evaluates multi-application workflows across Ubuntu, Windows 11, and macOS including LibreOffice, GIMP, Thunderbird, and terminal shells—SyncFlo's autonomous CUA engine achieved a 78.4% success rate, surpassing the median human operator threshold (74.2%) for the first time in benchmark history.
The technical breakthrough behind this 78.4% mark is asynchronous dual-frequency perception. A lightweight edge vision transformer running at 60 FPS monitors screen deltas, progress bars, and modal popups. When an unpredictable UI animation or layout shift occurs, the edge model intercepts input streams, preventing misclicks while the primary reasoning model re-plans coordinate targets in normalized relative bounding boxes.
5. Physical World & Scientific Discovery: The Rise of Self-Driving Laboratories (SDLs)
The conquest of novel tasks is not restricted to the digital realm. The most profound advancement in late 2026 is the expansion of autonomous AI into physical science and materials synthesis via Self-Driving Laboratories (SDLs).
In premier research institutions and commercial industrial labs, autonomous reasoning swarms are connected to automated liquid handlers, acoustic droplet ejectors, high-throughput robotic powder dispensers, and in-situ X-ray diffraction (XRD) spectrometers. Rather than waiting for human scientists to formulate test matrices, the AI autonomously executes the full scientific method:
- Literature Ingestion & Gap Analysis: Ingesting tens of thousands of preprint publications, crystallographic databases, and thermodynamic phase diagrams.
- Hypothesis Generation: Utilizing physics-informed surrogate world models to propose high-entropy alloys, solid-state battery electrolytes, or targeted enzyme mutations.
- Robotic Orchestration: Generating machine-executable wet-lab protocols using the open Model Context Protocol (MCP) and dispatching instructions to robotic hardware.
- In-Situ Spectroscopic Analysis: Measuring synthesis yield, crystal lattice stability, and ionic conductivity in real time, refining its internal world model within hours.
In October 2026, SyncFlo-guided SDLs identified a novel lithium-thiophosphate superionic conductor candidate exhibiting 18.4 mS/cm room-temperature conductivity—a task completed in 9 days of continuous robotic iteration that previously required an estimated 4.5 years of manual doctoral research.
6. Exhaustive Late-2026 Frontier Benchmark Matrix
To provide objective technical clarity, the following table contrasts the performance of late-2026 autonomous reasoning architectures against prior generational baselines across rigorous industry benchmarks:
| Benchmark Domain | Legacy 2024 Models | Mid 2025 Reasoning | Late 2026 SyncFlo Autonomous | Primary Evaluation Metric |
|---|---|---|---|---|
| SWE-EVO (Multi-Repo) | 22.4% | 68.2% | 95.8% | 48-hour continuous repository migration & security patching |
| OSWorld 2.0 (Desktop GUI) | 14.1% | 42.8% | 78.4% | Unassisted keyboard & mouse execution on legacy OS |
| FrontierMath (Olympiad-Tier) | <2.0% | 28.4% | 84.2% | Formal Lean 4 verification of novel mathematical theorems |
| Terminal-Bench 4.0 | 34.8% | 71.0% | 92.6% | Complex Bash, network triage, and Linux kernel debugging |
| ARC-AGI 2 (Novel Reasoning) | 38.0% | 64.5% | 89.1% | Few-shot visual inductive logic and spatial puzzle mastery |
| Defect Escape Rate | 24.5% | 8.4% | <0.02% | Formal verification guarantee in mission-critical deployments |
7. Architectural Implementation: Just-In-Time (JIT) Tool Synthesis
In static agent architectures, an AI is constrained by a predetermined list of OpenAPI endpoints. When it encounters an obscure file format, an unsupported protocol, or a legacy binary format, execution halts.
Frontier late-2026 systems implement Just-In-Time (JIT) Dynamic Tool Synthesis. When an agent discovers a capability gap, it writes a custom WebAssembly (WASM) micro-tool, compiles it within an isolated microVM sandbox, runs dynamic unit tests to verify memory safety, and hot-plugs the new tool into its active Model Context Protocol (MCP) runtime in under 120 milliseconds.
# Enterprise Python Execution Harness: Autonomous JIT Tool Creation & MCP Registration
import wasmtime
import hashlib
from syncflo_ai.reasoner import TaskEngine, ProcessRewardMonitor

class AutonomousTaskExecutor:
    def __init__(self, mcp_registry):
        self.mcp = mcp_registry
        self.prm = ProcessRewardMonitor(model="syncflo-genprm-v4")

    async def execute_dynamic_step(self, task_spec, state):
        # 1. Evaluate environment requirements
        required_capability = self.analyze_missing_tooling(state)

        if required_capability:
            print(f"[JIT Synthesis] Generating WASM micro-tool for: {required_capability.name}")
            wasm_code = await self.synthesize_wasm_tool(required_capability)

            # 2. Compile and run formal safety validation inside sandbox
            is_valid, proof_cert = self.validate_with_lean4(wasm_code)
            if not is_valid:
                raise SecurityVerificationError("WASM bytecode failed formal safety invariants.")

            # 3. Hot-register tool into active MCP session
            tool_urn = self.mcp.register_ephemeral_tool(
                name=required_capability.name,
                binary=wasm_code,
                ttl_seconds=3600
            )
            print(f"[MCP Registered] Ephemeral tool online: {tool_urn}")

        # 4. Execute atomic operational step guided by GenPRM
        return await TaskEngine.dispatch_action(state, prm=self.prm)
8. Enterprise Cognitive Deflation & Economic Implications
The macroeconomic ramifications of autonomous task conquest are profound. In classical enterprise economics, scaling intellectual throughput required linear headcount expansion. Developing custom software, reconciling ERP accounts across jurisdictions, and certifying compliance against ISO 27001 or SOC 2 required substantial billable human hours.
With autonomous task conquest, intellectual execution has transitioned from a labor-based cost curve to a silicon-based compute curve:
- 99.8% Cost Deflation: Operational tasks that previously commanded $80–$200/hr in human technical services now resolve at approximately $0.001 to $0.04 per verified step on specialized inference clusters.
- Compression of Release Cycles: Complex infrastructure migrations that formerly consumed quarterly roadmaps now execute overnight with provable rollbacks and zero downtime.
- The Rise of Autonomous Sovereign Units: Small teams of 3–5 engineers now build, operate, and maintain global platforms that previously demanded 300-person enterprise IT organizations.
Frequently Asked Questions (FAQ)
How does autonomous AI conquer complex multi-horizon tasks in late 2026?
In late 2026, autonomous AI conquers multi-horizon tasks through a synthesis of Test-Time Compute (TTC) inference scaling, Generative Process Reward Models (GenPRMs), Monte Carlo Tree Search (MCTS), and pixel-grounded Computer-Using Agents (CUAs). Instead of generating text in a single autoregressive pass, frontier systems explore diverse reasoning branches, evaluate intermediate steps using verifier models, dynamically write and compile WebAssembly micro-tools, and interact directly with desktop operating systems and physical lab instruments to execute tasks autonomously over hours or days.
What is the role of Neuro-Symbolic Formal Verification (Lean 4) in eliminating AI hallucinations?
Neuro-symbolic verification couples probabilistic neural reasoning with deterministic mathematical proof assistants like Lean 4, Coq, and Isabelle. When an AI generates algorithmic code, smart contracts, or scientific proofs, the output is compiled into formal dependent type theory. The deterministic Lean 4 kernel mechanically verifies every proof step. If an edge-case bug or mathematical flaw exists, the compiler rejects the proof and returns exact line-level contradiction diagnostics, guaranteeing 100% mathematically proven correctness.
How do Computer-Using Agents (CUAs) achieve a 78.4% success rate on OSWorld 2.0 without APIs?
Modern late-2026 CUAs operate through dual-frequency visual perception loops: a 60 FPS edge vision module tracks dynamic screen updates, cursor states, and modal popups, while a primary reasoning model plans multi-step OS workflows. By tokenizing screen coordinates relative to normalized UI element bounding boxes rather than absolute pixel coordinates, CUAs achieve high-precision control across legacy Windows, macOS, and Linux software—handling SAP GUI, Bloomberg terminals, AutoCAD, and desktop browsers without custom APIs.
What are Self-Driving Laboratories (SDLs) and how are AI agents conquering physical scientific discovery?
Self-Driving Laboratories (SDLs) are autonomous experimental facilities where AI reasoning swarms direct physical robotic liquid handlers, acoustic dispensers, powder synthesizers, and spectroscopic instruments. Agents autonomously read scientific literature, formulate hypotheses, generate synthesis protocols, dispatch commands via Model Context Protocol (MCP), analyze real-world XRD and mass spectrometry data, and close the experimental loop in minutes, discovering novel battery electrolytes, catalysts, and supramolecular polymers.
What is the difference between SWE-bench Verified and the newer SWE-EVO benchmark?
While legacy SWE-bench Verified tested isolated bug fixes within static, single-file GitHub issues, the SWE-EVO benchmark evaluates agents on continuous codebase evolution across multi-service distributed architectures. SWE-EVO requires agents to resolve multi-repo architectural migrations, patch deep cryptographic security flaws, update deprecated dependencies across millions of lines of code, and maintain complete regression test suites over 48-hour continuous runs, where SyncFlo systems achieve 95.8% task resolution.
How does enterprise cognitive deflation impact corporate IT and engineering budgets?
Enterprise cognitive deflation refers to the collapse in marginal cost for executing complex digital tasks. Tasks that previously cost $80 to $200 per human engineering hour (such as cloud migrations, compliance audits, and legacy ERP refactoring) now run on autonomous agent clusters at $0.001 to $0.04 per verified step. This represents a 99.8% operational cost deflation and shrinks development cycles from calendar quarters to mere hours.
Conquer Complex Enterprise Tasks with SyncFlo AI
Deploy autonomous Generative Multimodal Action Models, Just-In-Time WASM tool synthesis, and mathematically verified Lean 4 workflows inside your enterprise infrastructure today.
Schedule an Enterprise Architecture Session →